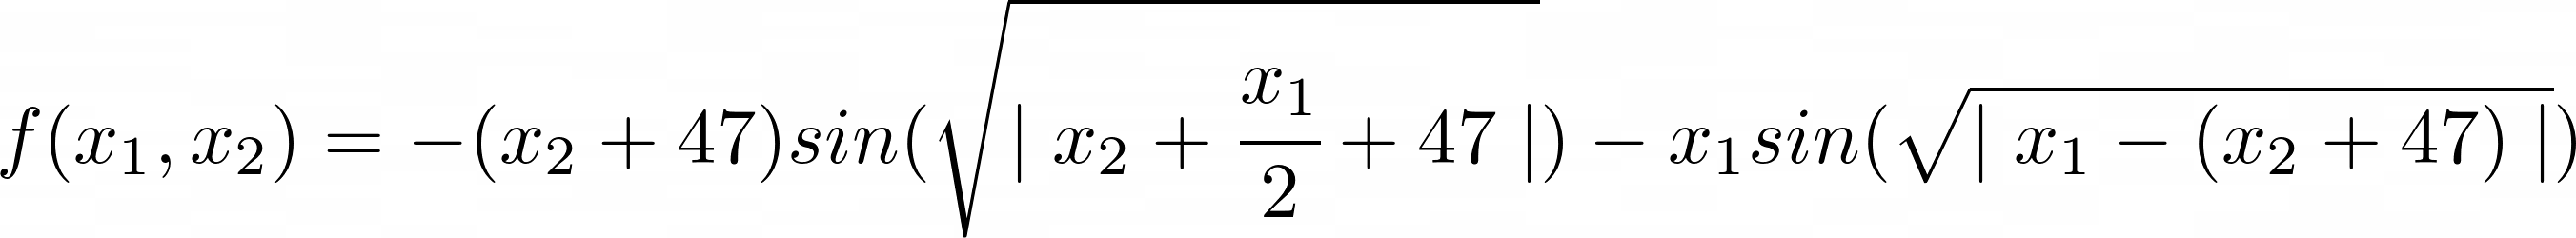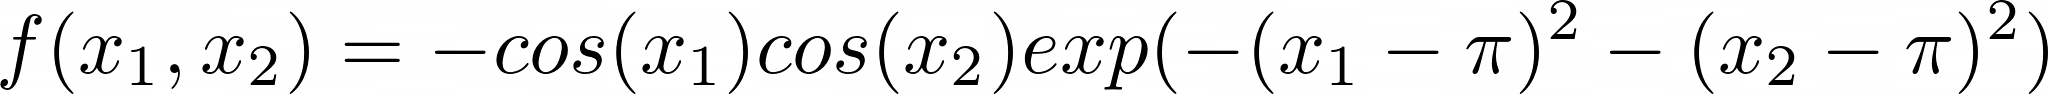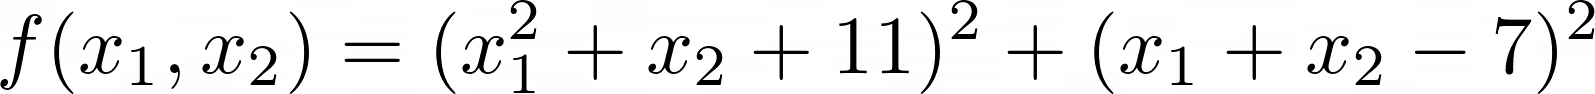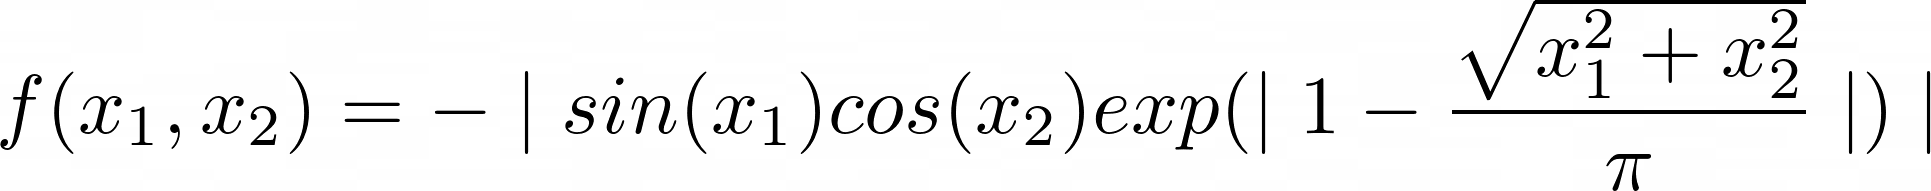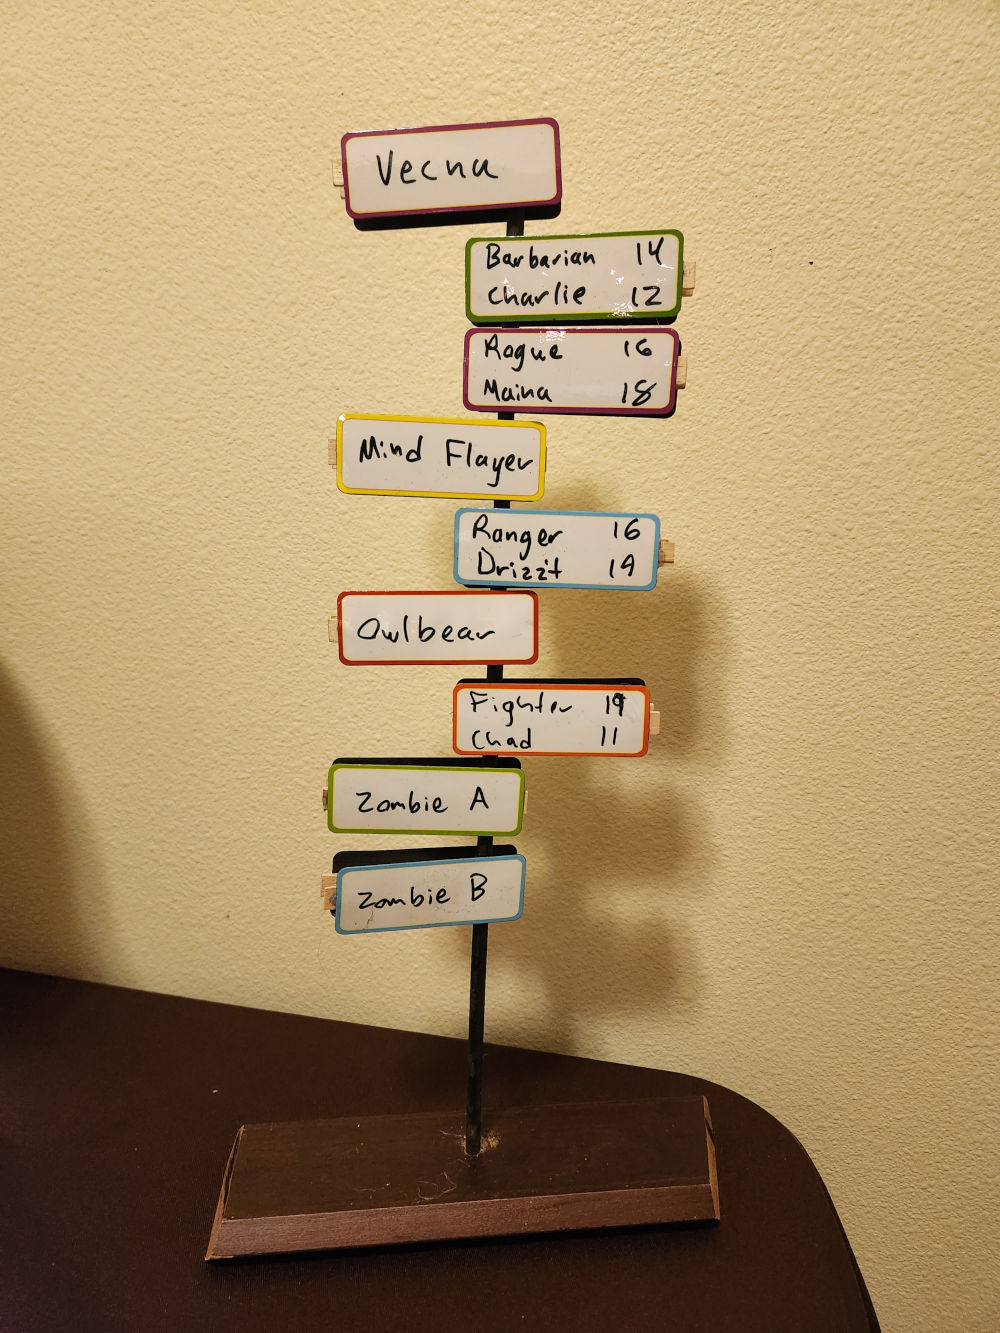<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://jayspeidell.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://jayspeidell.github.io/" rel="alternate" type="text/html" /><updated>2026-04-01T14:49:10-07:00</updated><id>https://jayspeidell.github.io/feed.xml</id><title type="html">Jay Speidell</title><subtitle>A Professional Portfolio</subtitle><author><name>Jay Speidell</name><email>jayspeidell@gmail.com</email></author><entry><title type="html">PySwarms - Open Source Software Contribution</title><link href="https://jayspeidell.github.io/posts/pyswarms/" rel="alternate" type="text/html" title="PySwarms - Open Source Software Contribution" /><published>2024-06-12T00:00:00-07:00</published><updated>2024-06-12T00:00:00-07:00</updated><id>https://jayspeidell.github.io/posts/pyswarms</id><content type="html" xml:base="https://jayspeidell.github.io/posts/pyswarms/"><![CDATA[<p>To learn more about collaborative development with version control systems as well as contributing to open source projects on GitHub, I made two contributions to the PySwarms project. PySwarms is a Python module for particle swarm optimization research.</p>

<h1 id="tools-used">Tools Used</h1>

<ul>
  <li>Python</li>
  <li>Jupyter Notebooks</li>
  <li>Unit Testing with PyTest</li>
  <li>Git &amp; GitHub</li>
</ul>

<h1 id="my-contributions">My Contributions</h1>

<p>I made the following contributions to the project:</p>
<ul>
  <li><a href="#improved-the-plotter-module">Improved the Plotter Module</a></li>
  <li><a href="#added-objective-functions">Added Objective Functions</a></li>
</ul>

<h2 id="improved-the-plotter-module">Improved The Plotter Module</h2>

<p><a href="https://github.com/ljvmiranda921/pyswarms/pull/172" target="_blank">View Pull Request on GitHub.</a></p>

<p>Bug fix: Added ‘z-axis’ to formatters/Designer attribute ‘labels’ to prevent index out of range error when plotting in 3D. Also added a third dimension to ‘limits’ for the same reason.</p>

<p>New feature: I added a colormaps property to the Designer class in formatters.py to allow the user to choose whichever one they want. It uses the same style as other properties of the class, and the module imports matplotlib.cm to validate both types of colormaps in matplotlib. I edited plotters/plot_countour to initialize a Designer object with a default colormap if none is provided. I’ve tested with every category of colormap as well as custom colormaps and verified that it is working as intended.</p>

<p>Default parameter change: Mesher.delta from 0.001 to 0.1. This makes it safe to run many of the functions on an average computer. With 0.001, the mesher object grows very quickly.</p>

<p><a href="/images/pyswarms/ploter.jpg"></a></p>

<h2 id="added-objective-functions">Added Objective Functions</h2>

<p><a href="https://github.com/ljvmiranda921/pyswarms/pull/168/commits/b5a3afdb6a3087cce64ec08f554ae034936eb553" target="_blank">View Objective Function Commit on GitHub.</a></p>

<p><a href="https://github.com/ljvmiranda921/pyswarms/pull/168">View Pull Request on GitHub.</a></p>

<p><a href="/images/pyswarms/Objective Functions Demo.ipynb">Download a demo notebook.</a></p>

<p>I cleaned up and fixed existing functions with TODO tags and implemented Cross-in-Tray, Easom, Eggholder, Himmelblau’s, Holder Table, and Three Hump Camel functions. The file was getting long so I also alphabetized the functions and made a simple table of contents. I also added unit tests for the new objective functions.</p>

<h3 id="cross-in-tray-function">Cross-in-Tray Function</h3>

<p><img src="/images/pyswarms/cross-in-tray.png" alt="" /></p>

<div class="flexible-container">
<iframe src="/images/pyswarms/cross_in_tray.mp4" type="video/mp4"> frameborder="0" style="border:0"&gt;</iframe>
</div>

<h3 id="eggholder-function">Eggholder Function</h3>

<p><img src="/images/pyswarms/eggholder.png" alt="" /></p>

<div class="flexible-container">
<iframe src="/images/pyswarms/eggholder.mp4" type="video/mp4"> frameborder="0" style="border:0"&gt;</iframe>
</div>

<h3 id="easom-function">Easom Function</h3>

<p><img src="/images/pyswarms/easom.png" alt="" /></p>

<div class="flexible-container">
<iframe src="/images/pyswarms/easom.mp4" type="video/mp4"> frameborder="0" style="border:0"&gt;</iframe>
</div>

<h3 id="himmelblau-function">Himmelblau Function</h3>

<p><img src="/images/pyswarms/himmelblau.png" alt="" /></p>

<div class="flexible-container">
<iframe src="/images/pyswarms/himmelblau.mp4" type="video/mp4"> frameborder="0" style="border:0"&gt;</iframe>
</div>

<h3 id="holder-table-function">Holder Table Function</h3>

<p><img src="/images/pyswarms/holder_table.png" alt="" /></p>

<div class="flexible-container">
<iframe src="/images/pyswarms/holder_table.mp4" type="video/mp4"> frameborder="0" style="border:0"&gt;</iframe>
</div>

<h3 id="three-hump-camel-function">Three Hump Camel Function</h3>

<p><img src="/images/pyswarms/three_hump_camel.png" alt="" /></p>

<div class="flexible-container">
<iframe src="/images/pyswarms/three_hump_camel.mp4" type="video/mp4">  frameborder="0" style="border:0"&gt;</iframe>
</div>]]></content><author><name>Jay Speidell</name><email>jayspeidell@gmail.com</email></author><category term="data science" /><summary type="html"><![CDATA[To learn more about collaborative development with version control systems as well as contributing to open source projects on GitHub, I made two contributions to the PySwarms project. PySwarms is a Python module for particle swarm optimization research.]]></summary></entry><entry><title type="html">DIY Initiative Tracker for Dungeons &amp;amp; Dragons</title><link href="https://jayspeidell.github.io/posts/2022/12/18/dnd-initiative-guide/" rel="alternate" type="text/html" title="DIY Initiative Tracker for Dungeons &amp;amp; Dragons" /><published>2022-12-18T00:00:00-08:00</published><updated>2022-12-18T00:00:00-08:00</updated><id>https://jayspeidell.github.io/posts/2022/12/18/dnd-initiative-guide</id><content type="html" xml:base="https://jayspeidell.github.io/posts/2022/12/18/dnd-initiative-guide/"><![CDATA[<p>I wanted a vertical initiative tracker with wet/dry erase labels and enough space to hold a dozen or so trackers for when lots of people show up at the game show. I couldn’t find many options, so I came up with this using mostly stuff I had around the house.</p>

<p><img src="/images/minis/init-finished.jpg" style="width:100%" /></p>

<h1 id="what-you-need">What you need:</h1>

<ul>
  <li>Base (any block of wood)</li>
  <li>1/4 inch dowel</li>
  <li>Clothespins</li>
  <li>Dry erase magnets (Not using the magnets, but this is the only way I could find very small and semi-rigid dry erase material.) <a href="https://www.amazon.com/dp/B0983VRBTD">Amazon Link (not affiliate)</a></li>
  <li>Sandpaper</li>
  <li>Hot glue gun or other adhesive</li>
  <li>Drill with 1/4 inch bit</li>
</ul>

<h1 id="steps">Steps</h1>

<ol>
  <li>
    <p>Drill out the base and insert the dowel. Use the same size drill bit as your dowel for a snug fit. <img src="/images/minis/init-drill.jpg" style="width:100%" /></p>
  </li>
  <li>
    <p><strong>Sandpaper</strong> the magnets. This is vital, as adhesives will not stick to a smooth magnet. The hot glue sticks well after the surface has been roughened up.</p>
  </li>
  <li>
    <p>Glue a magnet on each side of the clothespins. <img src="/images/minis/init-glue.jpg" style="width:100%" /></p>
  </li>
  <li>
    <p>Play D&amp;D! This is a pretty easy project. I mainly just wanted to share the idea.</p>
  </li>
</ol>

<p><img src="/images/minis/init-finished.jpg" style="width:100%" /></p>]]></content><author><name>Jay Speidell</name><email>jayspeidell@gmail.com</email></author><category term="dungeons and dragons" /><summary type="html"><![CDATA[An easy to make initiative tracker for Dungeons & Dragons. Vertical, uses dry erase trackers, and packs up pretty small.]]></summary></entry><entry><title type="html">Easy Papercraft Dungeons &amp;amp; Dragons Miniatures</title><link href="https://jayspeidell.github.io/posts/2022/12/17/dnd-minis-guide/" rel="alternate" type="text/html" title="Easy Papercraft Dungeons &amp;amp; Dragons Miniatures" /><published>2022-12-17T00:00:00-08:00</published><updated>2022-12-17T00:00:00-08:00</updated><id>https://jayspeidell.github.io/posts/2022/12/17/dnd-minis-guide</id><content type="html" xml:base="https://jayspeidell.github.io/posts/2022/12/17/dnd-minis-guide/"><![CDATA[<ul>
  <li><a href="#Design">Design</a></li>
  <li><a href="#Printing">Printing</a></li>
  <li><a href="#Finishing">Finishing</a></li>
</ul>

<p><a href="https://drive.google.com/drive/folders/1wLiS7TZpydAwycuHnFGZaKWt1daqGgSg?usp=share_link">Google Drive link to templates, examples, and spreadsheet for document setup.</a>
(Examples shared use artwork from Rise of the Drow, published by AAW games. I have permission to share it, and would discourage sharing any minis you make without asking permission from the creators.)</p>

<p>Minis can be a time consuming and expensive aspect of the D&amp;D hobby. Even with a 3D printer, it still takes quite a bit of time and effort to get perfect prints at that scale and I really hate painting.</p>

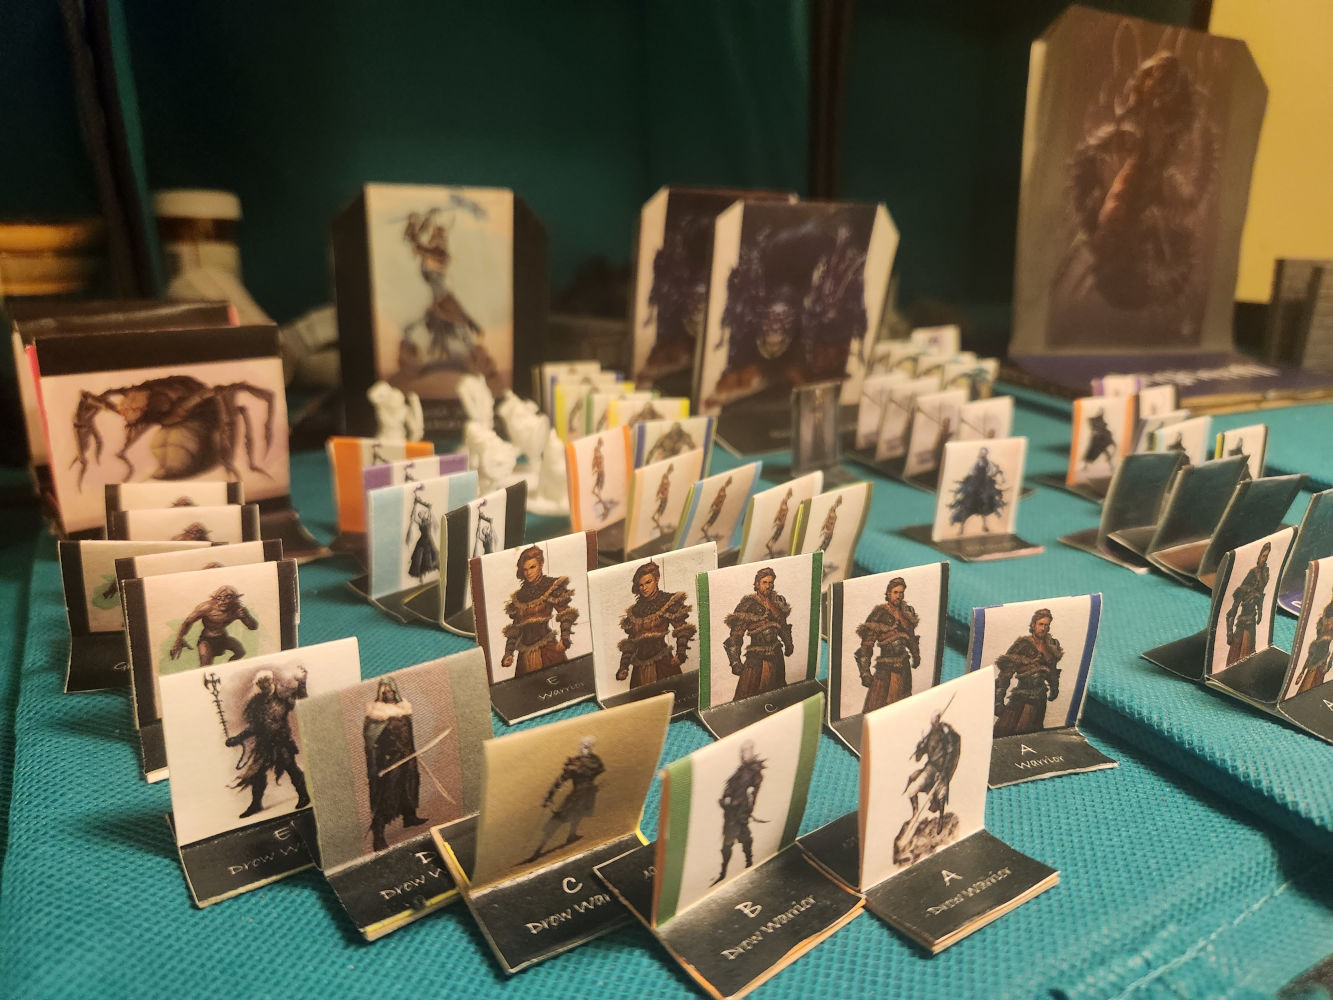
<p><img src="/images/minis/assortment.jpg" style="width:100%" /></p>

<p>That’s why I created this mini template for paper minis that stand up on their own. There are tons of templates for “standees”, but I wanted something that I can just grab and go and drop on the table. I’m really happy with how they turned out and use them in all of my games.</p>

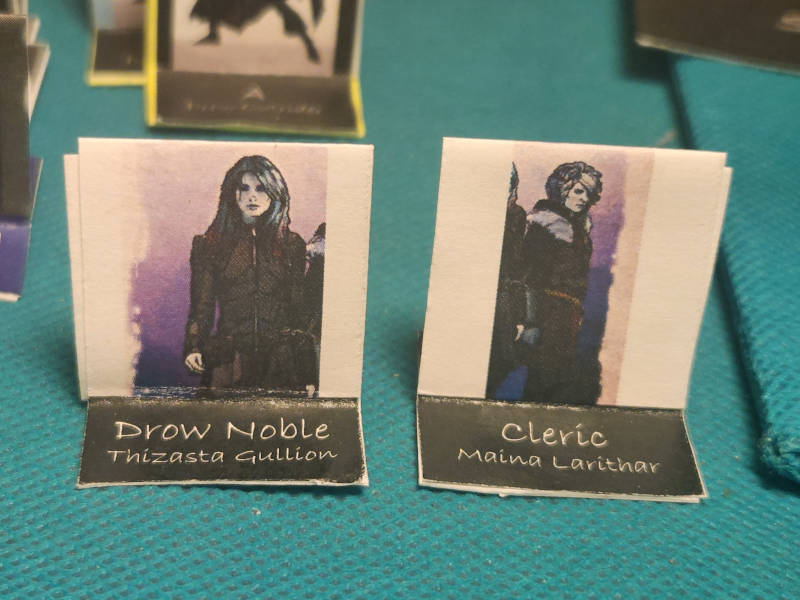
<p>It’s also very handy for creating one-off minis for named NPCs and having their name and art represented on the table.</p>

<p><img src="/images/minis/unique.jpg" style="width:100%" /></p>

<h1 id="design">Design</h1>

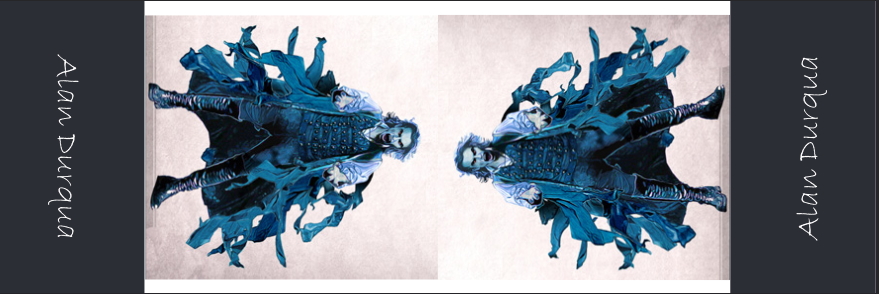
<p>This is what the minis look like in PDF form.</p>

<p><img src="/images/minis/alan.png" style="width:100%" /></p>

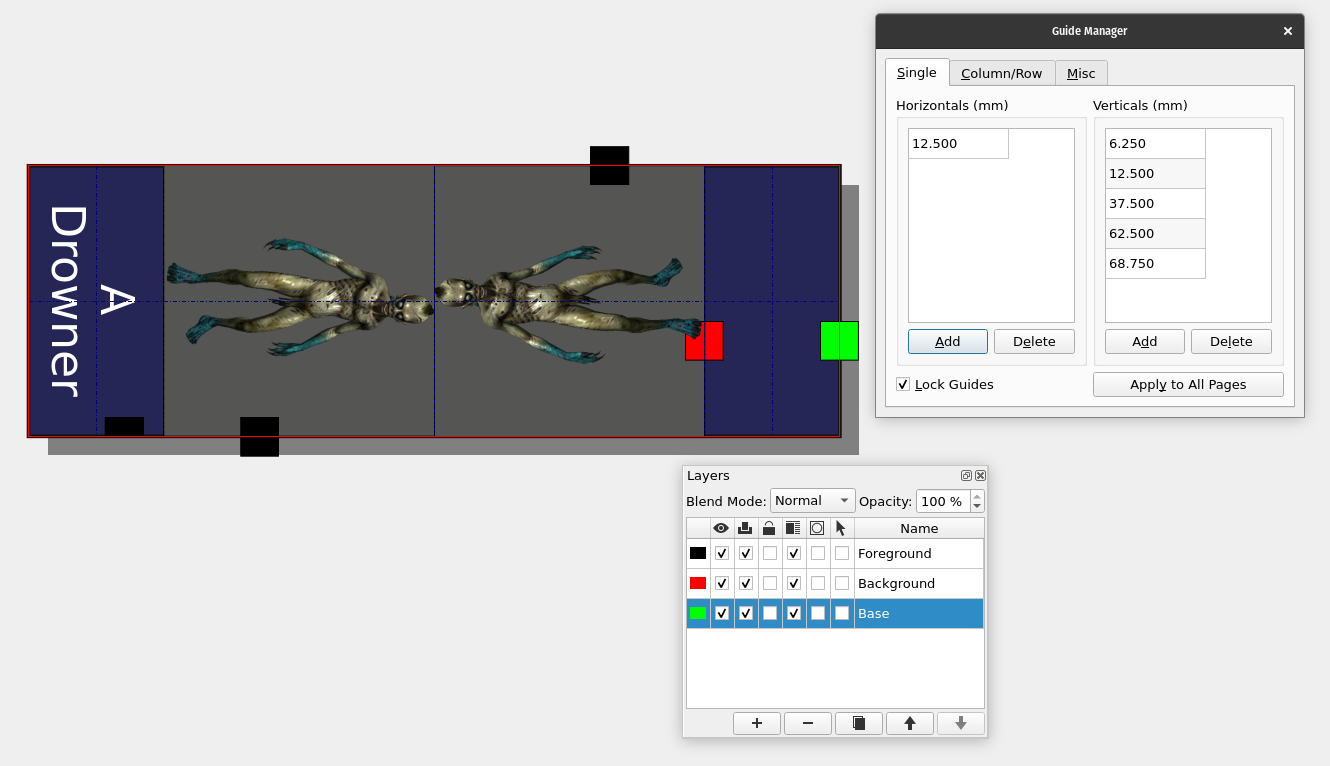
<p>I’ve published templates for Scribus and InDesign, <a href="https://drive.google.com/drive/folders/1wLiS7TZpydAwycuHnFGZaKWt1daqGgSg?usp=share_link">which you can download here</a>. I’ve also shared a spreadsheet with dimensions for recreating these templates in any design or photo editing software, <a href="https://docs.google.com/spreadsheets/d/1lFickwdqXbclH-I8550c6iuZcArN_kFF/edit?usp=share_link&amp;ouid=112011094715710279880&amp;rtpof=true&amp;sd=true">which you can download here</a>. (Dimensions are in millimeters.)</p>

<p>Use the dimensions in the spreadsheet to create the document size and guide lines for any given mini size. Here is an example in Scribus, where the guides menu is opened from Page &gt; manage Guides.</p>

<p><img src="/images/minis/scribus.png" style="width:100%" /></p>

<p>Swap out the image with one for your new mini.</p>

<p>A few suggestions:</p>
<ul>
  <li>Give it a name - even if you want to keep your monster name a secret, naming your mini can help you call it out on the table.</li>
  <li>Give it a letter - like in the old RPG games, it’s handy to have enemies labeled A, B, C, D, E, etc. This makes it easy to call out on a table.</li>
  <li>Text on one side - if you aren’t using front and back images, the text informs what direction the mini is facing.</li>
</ul>

<h1 id="printing">Printing</h1>

<p>This is pretty straightforward, but there’s a hack that only seems to work properly with Adobe Acrobat at this time. You can print a full sheet of these at scale to save paper. Select multiple pages per sheet in the printing options. Keep the scale at 100%, and select the appropriate number of rows and columns for your mini size.</p>

<p>Be aware that on all of the open source PDF apps I’ve tried, multiple sheets per print will only provide the option of scaling to maximize the fit for a given number of rows and columns rather than maintaining their scale with white space.</p>

<h1 id="finishing">Finishing</h1>

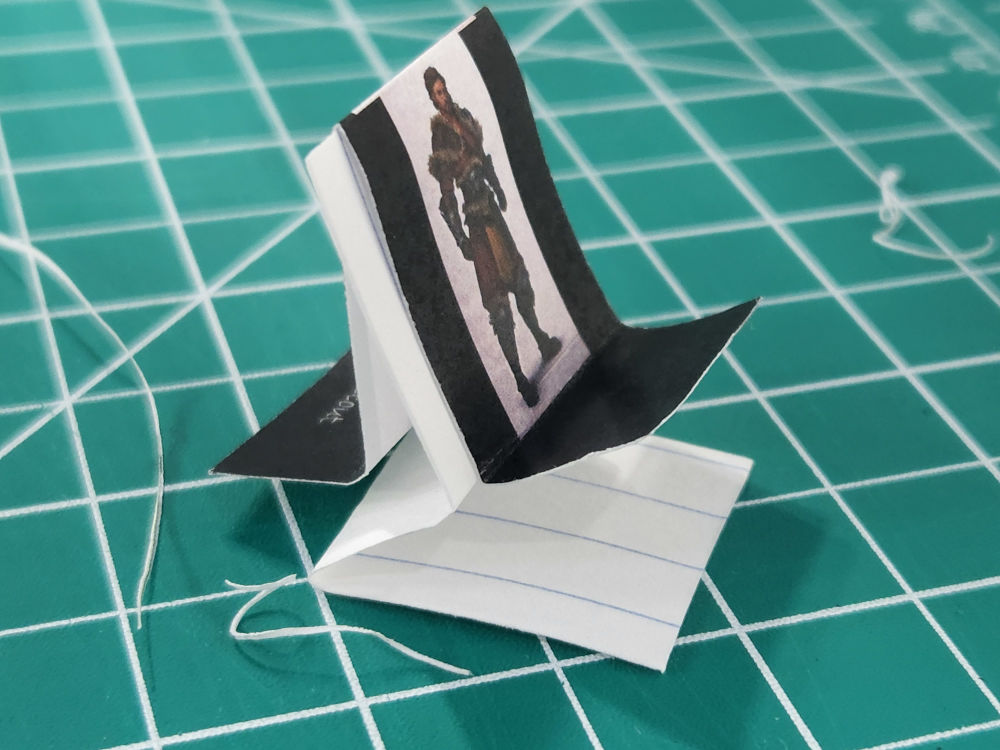
<p>Cut them out, along with 1” (or an appropriate width for your mini size) strips of index cards or card stock. Then fold and combine them and glue like in the picture below. Glue sticks work best, but if you don’t have that handy then wood glue works great.</p>

<p><img src="/images/minis/mini example.jpg" style="width:100%" /></p>

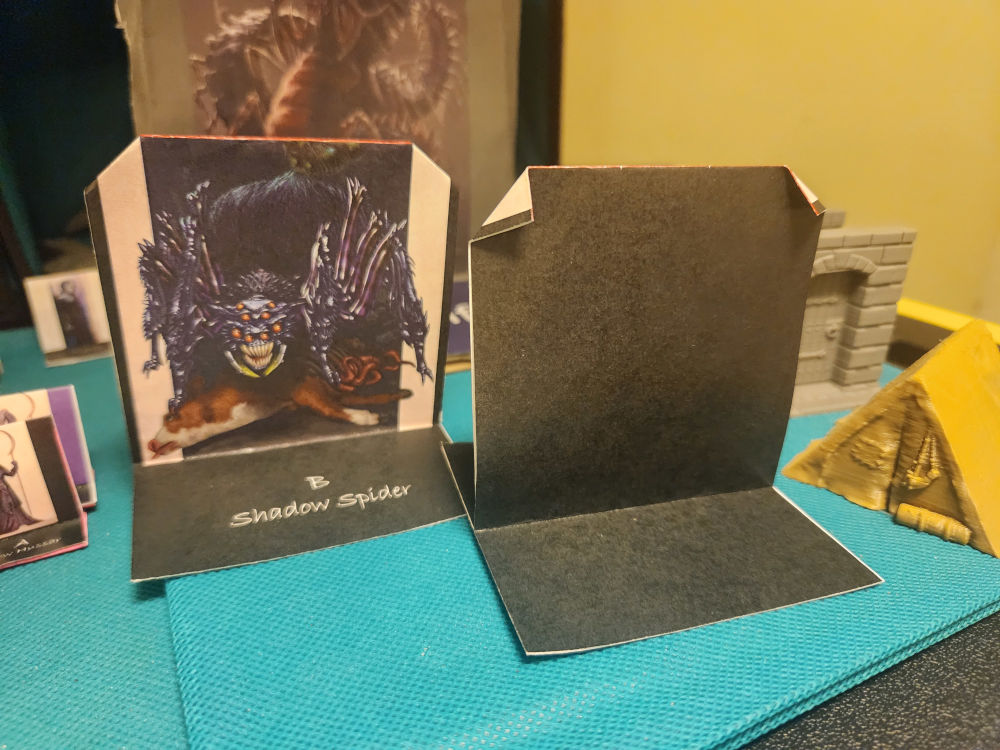
<p>For larger minis, you may not want to use card stock in the middle but instead just the base. They seem to maintain their shape better when the corners are crimped, like below, and use extra glue inside the fold. I’ve printed up to 7” tall gargantuan minis like this.</p>

<p><img src="/images/minis/fold.jpg" style="width:100%" /></p>]]></content><author><name>Jay Speidell</name><email>jayspeidell@gmail.com</email></author><category term="dungeons and dragons" /><summary type="html"><![CDATA[Minis for TTRPGs are expensive, time consuming to make, or both. Here is a way to make them cheap and easy with paper.]]></summary></entry><entry><title type="html">A Newbie’s Guide to Open Source Software Contributions</title><link href="https://jayspeidell.github.io/posts/2021/01/blog-post-2/" rel="alternate" type="text/html" title="A Newbie’s Guide to Open Source Software Contributions" /><published>2021-01-13T00:00:00-08:00</published><updated>2021-01-13T00:00:00-08:00</updated><id>https://jayspeidell.github.io/posts/2021/01/blog-post-2</id><content type="html" xml:base="https://jayspeidell.github.io/posts/2021/01/blog-post-2/"><![CDATA[<p>We all use open source software. Every time you take out your smartphone and connect to the internet you’re executing open source code, at every level from the kernel in your device’s operating system to the front end code your browser is rendering. Open source software is a powerful resource and a major driving force behind humanity’s rapid development of technology.</p>

<p>And it’s something you can participate in and contribute to with a surprisingly low barrier to entry.</p>

<p>I’m going to lay out a quick guide that can get you started in three steps: finding a project with issues that match your skill level and expertise, developing a working knowledge of the project, and making your first pull request.</p>

<p>And if this seems intimidating, it really isn’t. Open source developers are some of the most helpful people you’ll meet, and many of them will pull out beginner issues for new software engineers to learn how to collaborate with others.</p>

<p>Now let’s get started.</p>

<h1 id="finding-a-project">Finding a Project</h1>

<p>There are two ways that you can search for a project to contribute to. You can either start by looking for project that interest you and then find issues posted for that project, or you can search open issues for all projects that match your skills. The one thing these strategies have in common is that you’re looking for the beginner tag.</p>

<p>(You’ll want to open a spreadsheet or text file to keep track of several open issues you find in your search so that you can narrow down to one that is a good fit.)</p>

<p>The first is fairly straightforward: look up projects that you’ve already used on GitHub, click the issues tab, and add “label: beginner” to the search bar. If you’re interested in machine learning, Scikit-Learn is a popular project with active development that you could check out. See the open beginner issues <a href="https://github.com/scikit-learn/scikit-learn/issues?q=is%3Aissue+is%3Aopen+label%3A+beginner">here</a>. Note that most project won’t have beginner issues available.</p>

<p>The better strategy for finding issues that match your skillset is to search all open issues. Open up the <a href="https://github.com/search/advanced">advanced search on GitHub</a> and choose your desired language under “Advanced options” then scroll down to “Issues option” and select the “Open” status.</p>

<p>The key to your search is the issue labels. The first issue you want to search for is “<strong>good first issue</strong>.” These are issues posted by people explicitly in a teaching mindset. When I started learning software engineering before I even started on my Computer Science degree, an open source developers who posted an issue with this tag acted as a mentor and walked me through the process, from using Git to creating unit tests. (Shout out to <a href="https://github.com/ljvmiranda921">Lj Miranda</a> and <a href="https://github.com/whzup">wzup</a>!)</p>

<p>Here are a list of tags to search for:</p>

<ul>
  <li>good first issue - Mentioned above.</li>
  <li>beginner - Another popular tag for newbies.</li>
  <li>documentation - Not ready to write code? Documentation is an important part of projects.</li>
  <li>bug - Fixing a bug can be easier than implementing a feature in an unfamiliar project.</li>
</ul>

<p>Make a list of the issues that look cool. When you’ve found a decent amount, now you want to dive in and see if this is something you can really tackle. Open up the issue and read it carefully, then locate the code it relates to. How to do this varies greatly. Sometimes there’s a link and sometimes it’s pretty straightforward to click through the folders and find the module. If you get hung up, just introduce yourself in a comment on the issue and ask for a link so you can check it out.</p>

<p>Once you’ve found a project that’s interesting and you feel confident approaching, it’s time to develop a working knowledge of the project.
Develop a Working Knowledge of the Project</p>

<p>This is actually the most difficult step, especially if you don’t have experience jumping into an existing project before. You know how it’s easy to read a book, yet difficult to write one? Code is the opposite. Writing your own code is easy, reading other people’s code is challenging.</p>

<p>The first step? Use the software! Download and run a tutorial, run through an example exercise, or otherwise get simple working experience with it. It’s easy to overlook this step, but it’s important to see the big picture and really understand what the software is doing and the impact that your contribution will have on it.</p>

<p>Next, dive into the main loop! Or if it doesn’t have one and is a library, poke around the modules. You want to see what’s happening when this code is run. What the top level classes are, what’s imported from various modules and where the code being executed is stored. Tracing these various paths through the code will help you develop a good sense of both the structure of project as well as the programming style of the development team.</p>

<p>Finally, dig into to the module or modules that your issue concerns. Familiarize yourself with the imports, how the classes and functions work, and how the imported code works. You want to get a broad understanding of this so that you can not only make your contribution, but ensure that you create appropriate unit test coverage for the code you are adding and avoid introducing bugs to project.</p>

<p>Also important is to keep an eye out for any inefficiencies, bugs, or areas of improvement. For example, <a href="https://jayspeidell.github.io/portfolio/project00-pyswarms/">when I was working on pyswarms</a>, I noticed that there was a default value for a variable that created unnecessarily large meshes representing objective functions. I also noticed that the color gradient couldn’t me customized. I made a separate issue to address fixes to the plotting module.</p>

<p>Now it’s time to make you contribution! But keep in mind, coding is only part of it.</p>

<h1 id="take-on-the-issue-and-make-your-first-pull-request">Take On the Issue and Make Your First Pull Request</h1>

<p>If you haven’t already, introduce yourself to the development team through comments on the issue. Let them know you’re joining the project and want to take this issue on. Then open and read the contribution guide.</p>

<p>And read the contribution guide again. Seriously, this is important. It will contain information about how to effectively collaborate with the team and deliver code that matches the rest of the project. In it, the developers will talk about things like code formatters that ensure style consistency, unit test guidelines, the continuous integration pipeline, and more. And if you don’t understand anything, look it up!</p>

<p>Now it’s time to start programming! This is the fun part. Solve whatever issue you’re working on, implement that new feature or squash a bug. Write unit tests if need be. <strong>Just keep in mind that you only work on one issue at a time.</strong> This is good etiquette for collaboration, it not only keeps things organized but makes it easy for the developers leading the project to integrate your contribution. (Feel free to work on issues in separate branches, one at a time means one issue per pull request.)</p>

<p>The end result of your work is going to be a “pull request.” This may be an unfamiliar term, because if you’ve only worked on solo or small group projects in school this is a feature of Git that you don’t really need. Pull requests are the core collaborative functionality of Git, and it’s how you request that the changes made in your personal fork of the project get merged into a branch of the main repository.</p>

<p>You’ll make the pull request, and it will be either accepted and merged into the development branch or it will be rejected with comments on how to improve your code. And your first pull request will probably be rejected, so don’t feel bad! This is a learning experience. Read through their comments, fix your code, and try again.</p>

<h1 id="you-did-it">You Did It!</h1>

<p>Congrats! Now it’s time to sit back and watch your code merged into the main branch at the next release. People are going to use your code, and you’ve made a small albeit significant contribution to the development of open source software.</p>

<h2 id="about-the-author">About the Author</h2>

<p>I’m a recent Computer Science graduate. I’ve built a career in marketing, but I love technology and picked up programming and machine learning as a hobby a few years ago. Decided to go back to school and earned a Computer Science degree with a 3.94 GPA while working full time. Awesome, right? Except for the whole graduating into a pandemic hiring freeze that stopped my career transition in its tracks.</p>

<p>I’m looking for software engineering roles. I prefer back end, stuff like APIs, machine learning, C++ and Python, etc. But the specific frameworks and languages don’t matter. Throw me at some challenging problems and I’ll get it done!</p>]]></content><author><name>Jay Speidell</name><email>jayspeidell@gmail.com</email></author><category term="software engineering" /><summary type="html"><![CDATA[We all use open source software. Every time you take out your smartphone and connect to the internet you’re executing open source code, at every level from the kernel in your device’s operating system to the front end code your browser is rendering. Open source software is a powerful resource and a major driving force behind humanity’s rapid development of technology.]]></summary></entry><entry><title type="html">A Newbie’s Guide to Open Source Software Contributions</title><link href="https://jayspeidell.github.io/posts/open-source-guide" rel="alternate" type="text/html" title="A Newbie’s Guide to Open Source Software Contributions" /><published>2021-01-13T00:00:00-08:00</published><updated>2021-01-13T00:00:00-08:00</updated><id>https://jayspeidell.github.io/posts/open-source-guide</id><content type="html" xml:base="https://jayspeidell.github.io/posts/open-source-guide"><![CDATA[<p>We all use open source software. Every time you take out your smartphone and connect to the internet you’re executing open source code, at every level from the kernel in your device’s operating system to the front end code your browser is rendering. Open source software is a powerful resource and a major driving force behind humanity’s rapid development of technology.</p>

<p>And it’s something you can participate in and contribute to with a surprisingly low barrier to entry.</p>

<p>I’m going to lay out a quick guide that can get you started in three steps: finding a project with issues that match your skill level and expertise, developing a working knowledge of the project, and making your first pull request.</p>

<p>And if this seems intimidating, it really isn’t. Open source developers are some of the most helpful people you’ll meet, and many of them will pull out beginner issues for new software engineers to learn how to collaborate with others.</p>

<p>Now let’s get started.</p>

<h1 id="finding-a-project">Finding a Project</h1>

<p>There are two ways that you can search for a project to contribute to. You can either start by looking for project that interest you and then find issues posted for that project, or you can search open issues for all projects that match your skills. The one thing these strategies have in common is that you’re looking for the beginner tag.</p>

<p>(You’ll want to open a spreadsheet or text file to keep track of several open issues you find in your search so that you can narrow down to one that is a good fit.)</p>

<p>The first is fairly straightforward: look up projects that you’ve already used on GitHub, click the issues tab, and add “label: beginner” to the search bar. If you’re interested in machine learning, Scikit-Learn is a popular project with active development that you could check out. See the open beginner issues <a href="https://github.com/scikit-learn/scikit-learn/issues?q=is%3Aissue+is%3Aopen+label%3A+beginner">here</a>. Note that most project won’t have beginner issues available.</p>

<p>The better strategy for finding issues that match your skillset is to search all open issues. Open up the <a href="https://github.com/search/advanced">advanced search on GitHub</a> and choose your desired language under “Advanced options” then scroll down to “Issues option” and select the “Open” status.</p>

<p>The key to your search is the issue labels. The first issue you want to search for is “<strong>good first issue</strong>.” These are issues posted by people explicitly in a teaching mindset. When I started learning software engineering before I even started on my Computer Science degree, an open source developers who posted an issue with this tag acted as a mentor and walked me through the process, from using Git to creating unit tests. (Shout out to <a href="https://github.com/ljvmiranda921">Lj Miranda</a> and <a href="https://github.com/whzup">wzup</a>!)</p>

<p>Here are a list of tags to search for:</p>

<ul>
  <li>good first issue - Mentioned above.</li>
  <li>beginner - Another popular tag for newbies.</li>
  <li>documentation - Not ready to write code? Documentation is an important part of projects.</li>
  <li>bug - Fixing a bug can be easier than implementing a feature in an unfamiliar project.</li>
</ul>

<p>Make a list of the issues that look cool. When you’ve found a decent amount, now you want to dive in and see if this is something you can really tackle. Open up the issue and read it carefully, then locate the code it relates to. How to do this varies greatly. Sometimes there’s a link and sometimes it’s pretty straightforward to click through the folders and find the module. If you get hung up, just introduce yourself in a comment on the issue and ask for a link so you can check it out.</p>

<p>Once you’ve found a project that’s interesting and you feel confident approaching, it’s time to develop a working knowledge of the project.
Develop a Working Knowledge of the Project</p>

<p>This is actually the most difficult step, especially if you don’t have experience jumping into an existing project before. You know how it’s easy to read a book, yet difficult to write one? Code is the opposite. Writing your own code is easy, reading other people’s code is challenging.</p>

<p>The first step? Use the software! Download and run a tutorial, run through an example exercise, or otherwise get simple working experience with it. It’s easy to overlook this step, but it’s important to see the big picture and really understand what the software is doing and the impact that your contribution will have on it.</p>

<p>Next, dive into the main loop! Or if it doesn’t have one and is a library, poke around the modules. You want to see what’s happening when this code is run. What the top level classes are, what’s imported from various modules and where the code being executed is stored. Tracing these various paths through the code will help you develop a good sense of both the structure of project as well as the programming style of the development team.</p>

<p>Finally, dig into to the module or modules that your issue concerns. Familiarize yourself with the imports, how the classes and functions work, and how the imported code works. You want to get a broad understanding of this so that you can not only make your contribution, but ensure that you create appropriate unit test coverage for the code you are adding and avoid introducing bugs to project.</p>

<p>Also important is to keep an eye out for any inefficiencies, bugs, or areas of improvement. For example, <a href="https://jayspeidell.github.io/portfolio/project00-pyswarms/">when I was working on pyswarms</a>, I noticed that there was a default value for a variable that created unnecessarily large meshes representing objective functions. I also noticed that the color gradient couldn’t me customized. I made a separate issue to address fixes to the plotting module.</p>

<p>Now it’s time to make you contribution! But keep in mind, coding is only part of it.</p>

<h1 id="take-on-the-issue-and-make-your-first-pull-request">Take On the Issue and Make Your First Pull Request</h1>

<p>If you haven’t already, introduce yourself to the development team through comments on the issue. Let them know you’re joining the project and want to take this issue on. Then open and read the contribution guide.</p>

<p>And read the contribution guide again. Seriously, this is important. It will contain information about how to effectively collaborate with the team and deliver code that matches the rest of the project. In it, the developers will talk about things like code formatters that ensure style consistency, unit test guidelines, the continuous integration pipeline, and more. And if you don’t understand anything, look it up!</p>

<p>Now it’s time to start programming! This is the fun part. Solve whatever issue you’re working on, implement that new feature or squash a bug. Write unit tests if need be. <strong>Just keep in mind that you only work on one issue at a time.</strong> This is good etiquette for collaboration, it not only keeps things organized but makes it easy for the developers leading the project to integrate your contribution. (Feel free to work on issues in separate branches, one at a time means one issue per pull request.)</p>

<p>The end result of your work is going to be a “pull request.” This may be an unfamiliar term, because if you’ve only worked on solo or small group projects in school this is a feature of Git that you don’t really need. Pull requests are the core collaborative functionality of Git, and it’s how you request that the changes made in your personal fork of the project get merged into a branch of the main repository.</p>

<p>You’ll make the pull request, and it will be either accepted and merged into the development branch or it will be rejected with comments on how to improve your code. And your first pull request will probably be rejected, so don’t feel bad! This is a learning experience. Read through their comments, fix your code, and try again.</p>

<h1 id="you-did-it">You Did It!</h1>

<p>Congrats! Now it’s time to sit back and watch your code merged into the main branch at the next release. People are going to use your code, and you’ve made a small albeit significant contribution to the development of open source software.</p>

<h2 id="about-the-author">About the Author</h2>

<p>I’m a recent Computer Science graduate. I’ve built a career in marketing, but I love technology and picked up programming and machine learning as a hobby a few years ago. Decided to go back to school and earned a Computer Science degree with a 3.94 GPA while working full time. Awesome, right? Except for the whole graduating into a pandemic hiring freeze that stopped my career transition in its tracks.</p>

<p>I’m looking for software engineering roles. I prefer back end, stuff like APIs, machine learning, C++ and Python, etc. But the specific frameworks and languages don’t matter. Throw me at some challenging problems and I’ll get it done!</p>]]></content><author><name>Jay Speidell</name><email>jayspeidell@gmail.com</email></author><category term="software engineering" /><summary type="html"><![CDATA[We all use open source software. Every time you take out your smartphone and connect to the internet you’re executing open source code, at every level from the kernel in your device’s operating system to the front end code your browser is rendering. Open source software is a powerful resource and a major driving force behind humanity’s rapid development of technology.]]></summary></entry><entry><title type="html">Galaxy Zoo Challenge - Image Classification with PyTorch</title><link href="https://jayspeidell.github.io/posts/galazy-zoo-challenge/" rel="alternate" type="text/html" title="Galaxy Zoo Challenge - Image Classification with PyTorch" /><published>2020-07-25T00:00:00-07:00</published><updated>2020-07-25T00:00:00-07:00</updated><id>https://jayspeidell.github.io/posts/galazy-zoo</id><content type="html" xml:base="https://jayspeidell.github.io/posts/galazy-zoo-challenge/"><![CDATA[<p><img src="/images/galaxy-zoo/header.png" style="width:100%" /></p>

<p>This is an image classification project that I completed for my independent study at Old Dominion University. I’m interested in astronomy and chose to do Kaggle’s <a href="https://www.kaggle.com/c/galaxy-zoo-the-galaxy-challenge" target="_blank">Galaxy Zoo Challenge</a>.</p>

<p>I’m going to walk you through my workflow for this project, including exploratory data analysis, image processing, and finally building a convolutional neural network (CNN) with PyTorch.</p>

<p><a href="/images/galaxy-zoo/CS497_proj_1_JUN_7.html" target="_blank">View the source Jupyter Notebook (HTML)</a>, which contains the full source code as well as my learning notes. Please excuse the spelling, as Jupyter does not have spellcheck!</p>

<h3 id="index">Index</h3>
<ol>
  <li><a href="#tools-used">Tools Used</a></li>
  <li><a href="#project-background">Project Background</a></li>
  <li><a href="#exploratory-data-analysis">Exploratory Data Analysis</a></li>
  <li><a href="#benchmarking">Benchmarking</a></li>
  <li><a href="#preprocessing">Preprocessing</a></li>
  <li><a href="#convolutional-neural-network">Convolutional Neural Network</a></li>
  <li><a href="#building-the-model">Building the Model</a></li>
  <li><a href="#closing-thoughts">Closing Thoughts</a></li>
</ol>

<h2 id="tools-used">Tools Used</h2>

<ul>
  <li>Numpy</li>
  <li>OpenCV</li>
  <li>Pandas</li>
  <li>Python Image Library</li>
  <li>PyTorch</li>
  <li>Scipy</li>
  <li>Scikit-Learn</li>
</ul>

<h2 id="project-background">Project Background</h2>

<p>This project is based on the <a href="https://www.kaggle.com/c/galaxy-zoo-the-galaxy-challenge" target="_blank">Galaxy Zoo Challenge</a> on Kaggle. Galaxy Zoo is a project to describe galaxies in the night sky using an innovative <a href="https://www.zooniverse.org/projects/zookeeper/galaxy-zoo" target="_blank">crowdsourcing tool</a>, where users answer a series of questions about the images they are looking at. The dataset consists of 61,578 images with corresponding labels.</p>

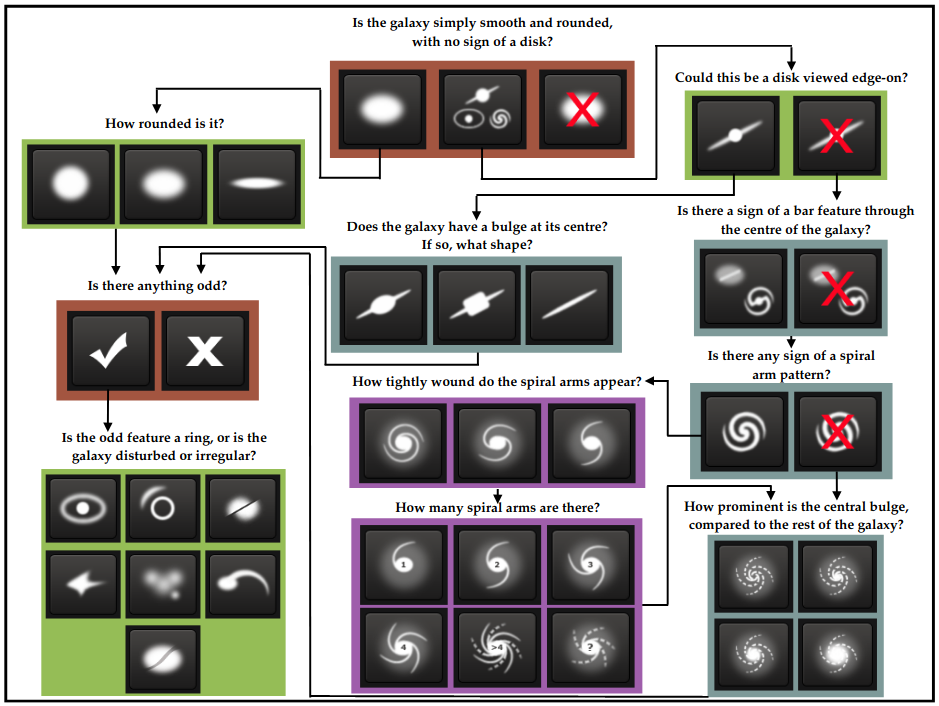
<p>The labels represent 37 classes of the format “ClassA.B”, where A represents the questions being as (from 1 to 11) and B represents the choices at the given level. This is different than a typical classification problem because each class represents an attribute, and most images will contain multiple attributes. The values represent the confidence of the crowd that a given answer is correct, from zero to one. The decision tree does not show every question to the user, but rather the questions shown are based on the previous answers.</p>

<p>Figure 1 shows a graphical representation from the <a href="https://arxiv.org/abs/1308.3496">Galaxy Zoo 2</a> research paper.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/galaxy-zoo/galaxy-zoo-flowchart.png" width="95%" />
  <br />
    <em>Figure 1: Willett, K. W., Lintott, C. J., Bamford, S. P., Masters, K. L., Simmons, B. D., Casteels, K. R. V., … Thomas, D. (2013). Galaxy Zoo 2: detailed morphological classifications for 304 122 galaxies from the Sloan Digital Sky Survey. Monthly Notices of the Royal Astronomical Society, 435(4), 2835–2860. doi: 10.1093/mnras/stt1458. Retrieved from [https://arxiv.org/abs/1308.3496](https://arxiv.org/abs/1308.3496) </em>
</p>

<p>My objective is the same as the Kaggle leaderboard scoring function, optimize the element-wise root mean-squared-error (RMSE). To evaluate that, I wrote the below function.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">RMSE</span><span class="p">(</span><span class="n">pred</span><span class="p">,</span> <span class="n">truth</span><span class="p">):</span>
    <span class="k">return</span> <span class="n">np</span><span class="p">.</span><span class="n">sqrt</span><span class="p">(</span> <span class="n">np</span><span class="p">.</span><span class="n">mean</span><span class="p">(</span> <span class="n">np</span><span class="p">.</span><span class="n">square</span><span class="p">(</span>
                <span class="n">np</span><span class="p">.</span><span class="n">array</span><span class="p">(</span><span class="n">pred</span><span class="p">).</span><span class="n">flatten</span><span class="p">()</span> <span class="o">-</span> <span class="n">np</span><span class="p">.</span><span class="n">array</span><span class="p">(</span><span class="n">truth</span><span class="p">).</span><span class="n">flatten</span><span class="p">()</span> <span class="p">)))</span>
</code></pre></div></div>

<h2 id="exploratory-data-analysis">Exploratory Data Analysis</h2>

<p>The objective of my exploratory data analysis was to get a better understanding of the dataset to better inform my preprocessing and deep learning strategies. I wanted to learn a bit about how the classes are distributed as well as how the galaxies are displayed in the images.</p>

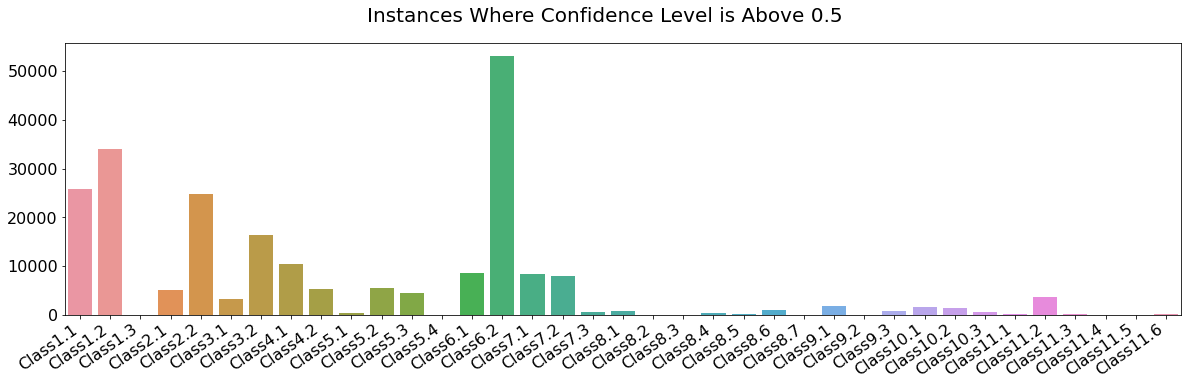
<p>The first thing I looked at was the instances of all classes where the confidence level was above 0.5. This is interesting to me because it will show me which classes are common and which are sparse, and the main actionable takeaway is whether I needed apply weights to the loss function. If the classes were all evenly distributed, I could use and out of the box loss function. If not, I would need to write one that applies weights to prevent the neural network from over-prioritizing classes where there isn’t enough data to effectively learn.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/galaxy-zoo/counts.png" width="95%" />
  <br />
    <em>Figure 2: Class counts where confidence level is 0.5 or above. </em>
</p>

<p>As you can see, there are a few dominant classes, a number of somewhat sparse classes, and a few extremely sparse classes. I also dug into the nine terminal classes, answers where the decision tree terminates.</p>

<p>Class1.3: 44
Class6.2: 53115
Class8.1: 886
Class8.2: 4
Class8.3: 16
Class8.4: 301
Class8.5: 202
Class8.6: 1022
Class8.7: 27</p>

<p>There are three ways the decision tree terminates: not a galaxy, not an odd galaxy, and if odd, what type of oddity is present. As we can see, nearly every image does display a galaxy and an overwhelming majority, about 86%, are not odd. Of those that are odd, most fall into only two categories.</p>

<p>The sparse classes are non-viable, and to compensate for this I wrote the following PyTorch loss function:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">weights</span> <span class="o">=</span> <span class="n">torch</span><span class="p">.</span><span class="n">tensor</span><span class="p">(</span><span class="n">np</span><span class="p">.</span><span class="nb">sum</span><span class="p">(</span><span class="n">y_train</span><span class="p">,</span> <span class="n">axis</span><span class="o">=</span><span class="mi">0</span><span class="p">)</span> <span class="o">/</span> <span class="n">np</span><span class="p">.</span><span class="nb">sum</span><span class="p">(</span><span class="n">y_train</span><span class="p">))</span>

<span class="k">def</span> <span class="nf">weighted_mse_loss</span><span class="p">(</span><span class="n">output</span><span class="p">,</span> <span class="n">targets</span><span class="p">,</span> <span class="n">weights</span><span class="p">):</span>
  <span class="c1"># Arguments are all PyTorch tensors
</span>  <span class="n">loss</span> <span class="o">=</span> <span class="p">(</span><span class="n">output</span> <span class="o">-</span> <span class="n">targets</span><span class="p">)</span> <span class="o">**</span> <span class="mi">2</span>
  <span class="n">loss</span> <span class="o">=</span> <span class="n">loss</span> <span class="o">*</span> <span class="n">weights</span><span class="p">.</span><span class="n">expand</span><span class="p">(</span><span class="n">loss</span><span class="p">.</span><span class="n">shape</span><span class="p">)</span> <span class="c1"># broadcast (37,) weight array to (n, 37).
</span>  <span class="n">loss</span> <span class="o">=</span> <span class="n">loss</span><span class="p">.</span><span class="n">mean</span><span class="p">(</span><span class="mi">0</span><span class="p">)</span>
  <span class="k">return</span> <span class="n">loss</span><span class="p">.</span><span class="nb">sum</span><span class="p">()</span>
</code></pre></div></div>

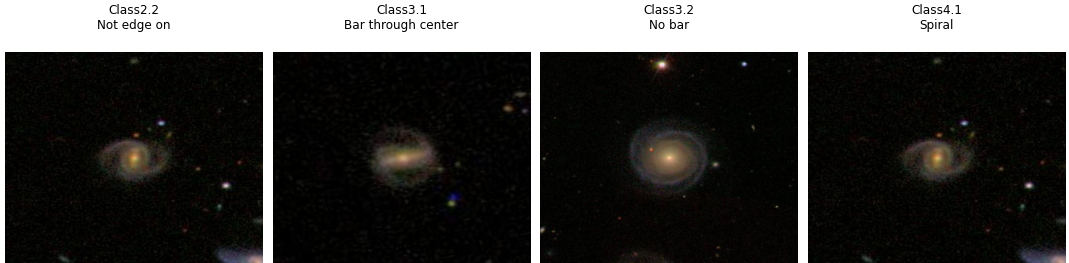
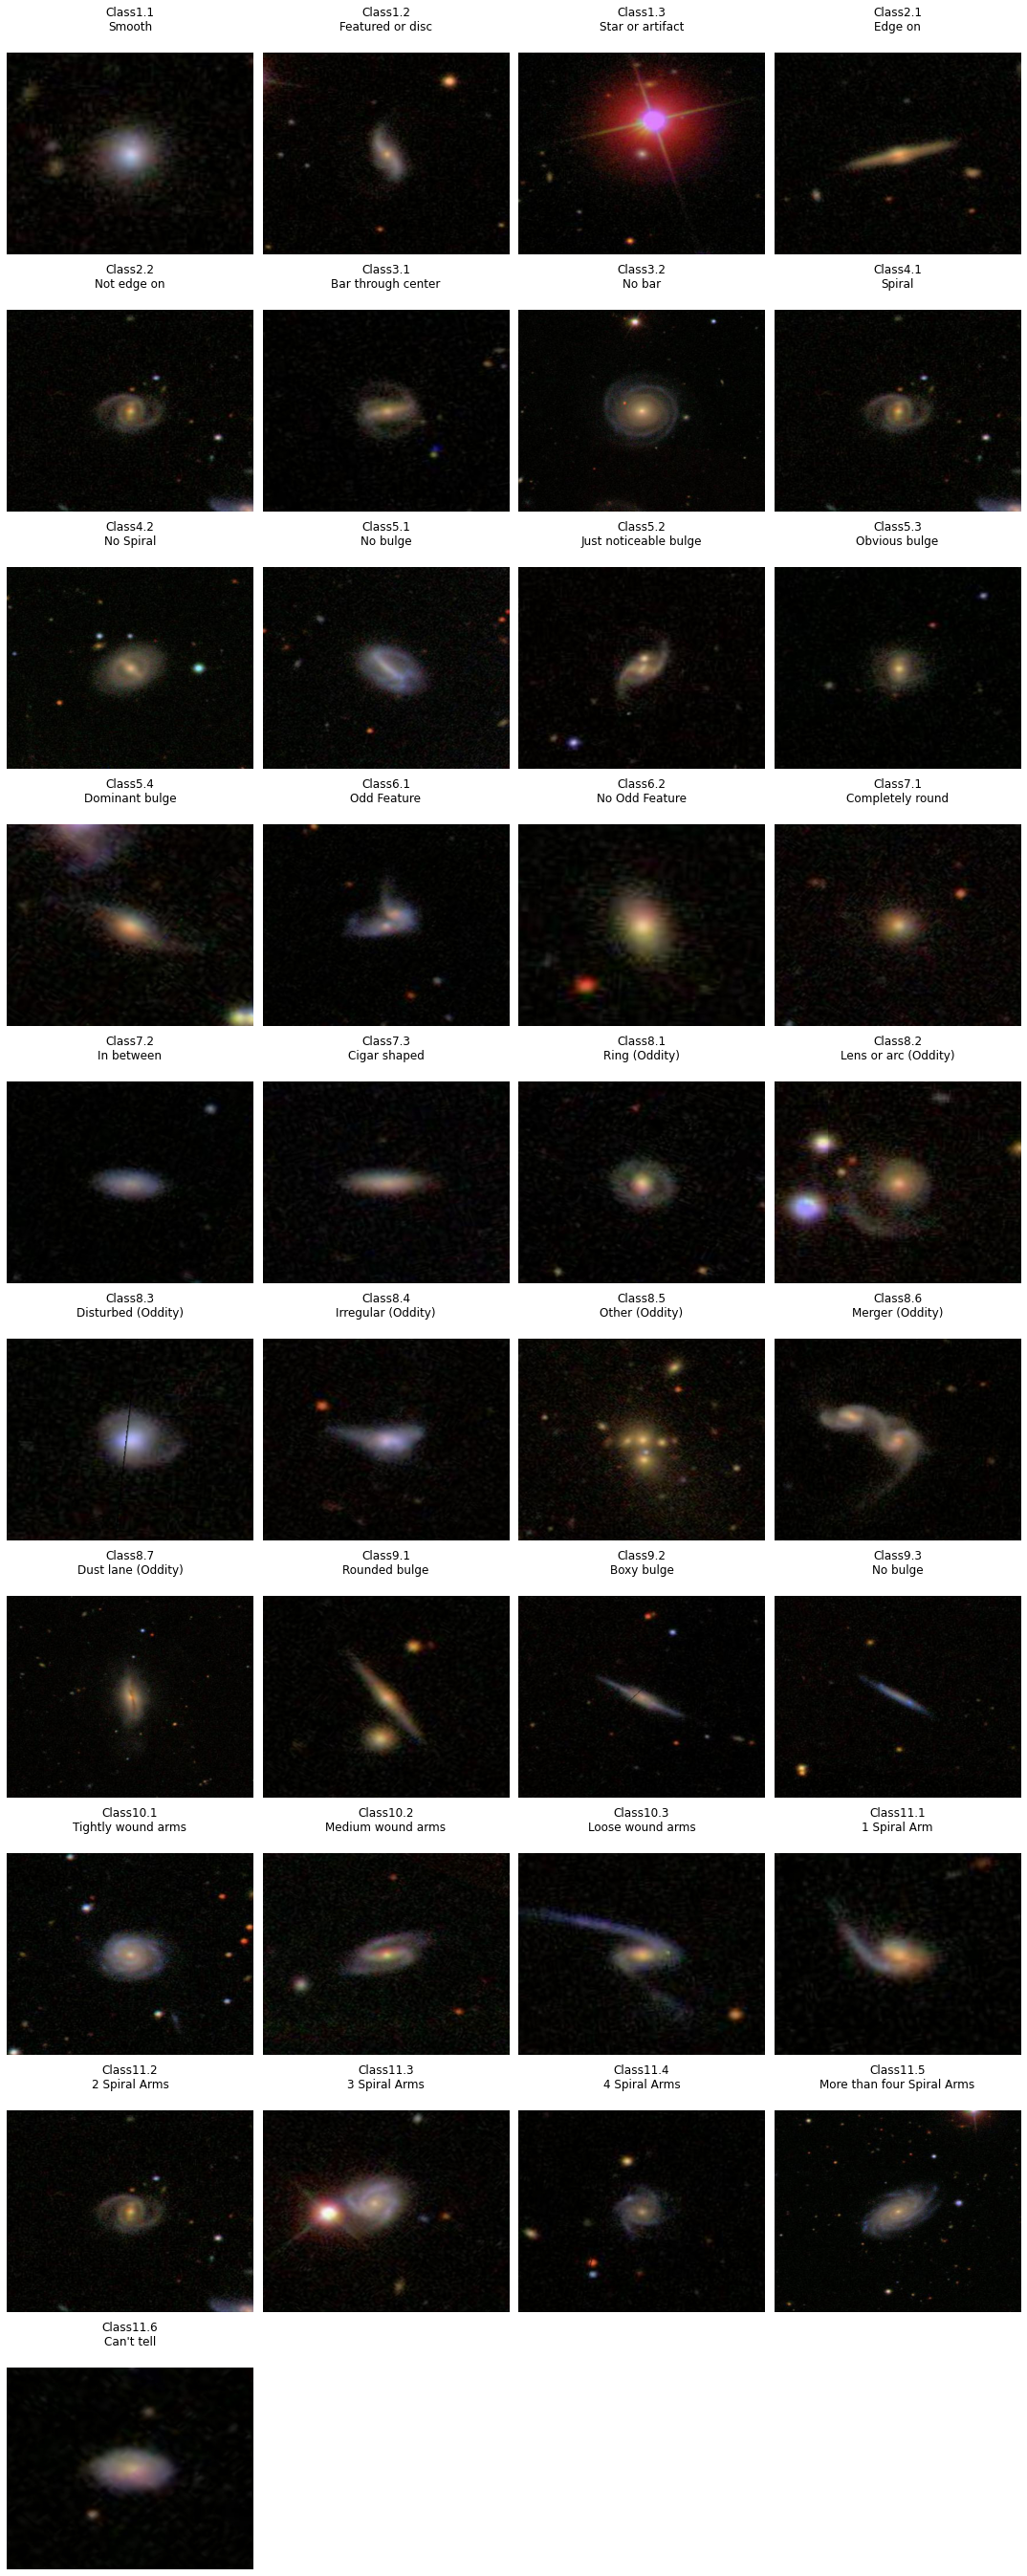
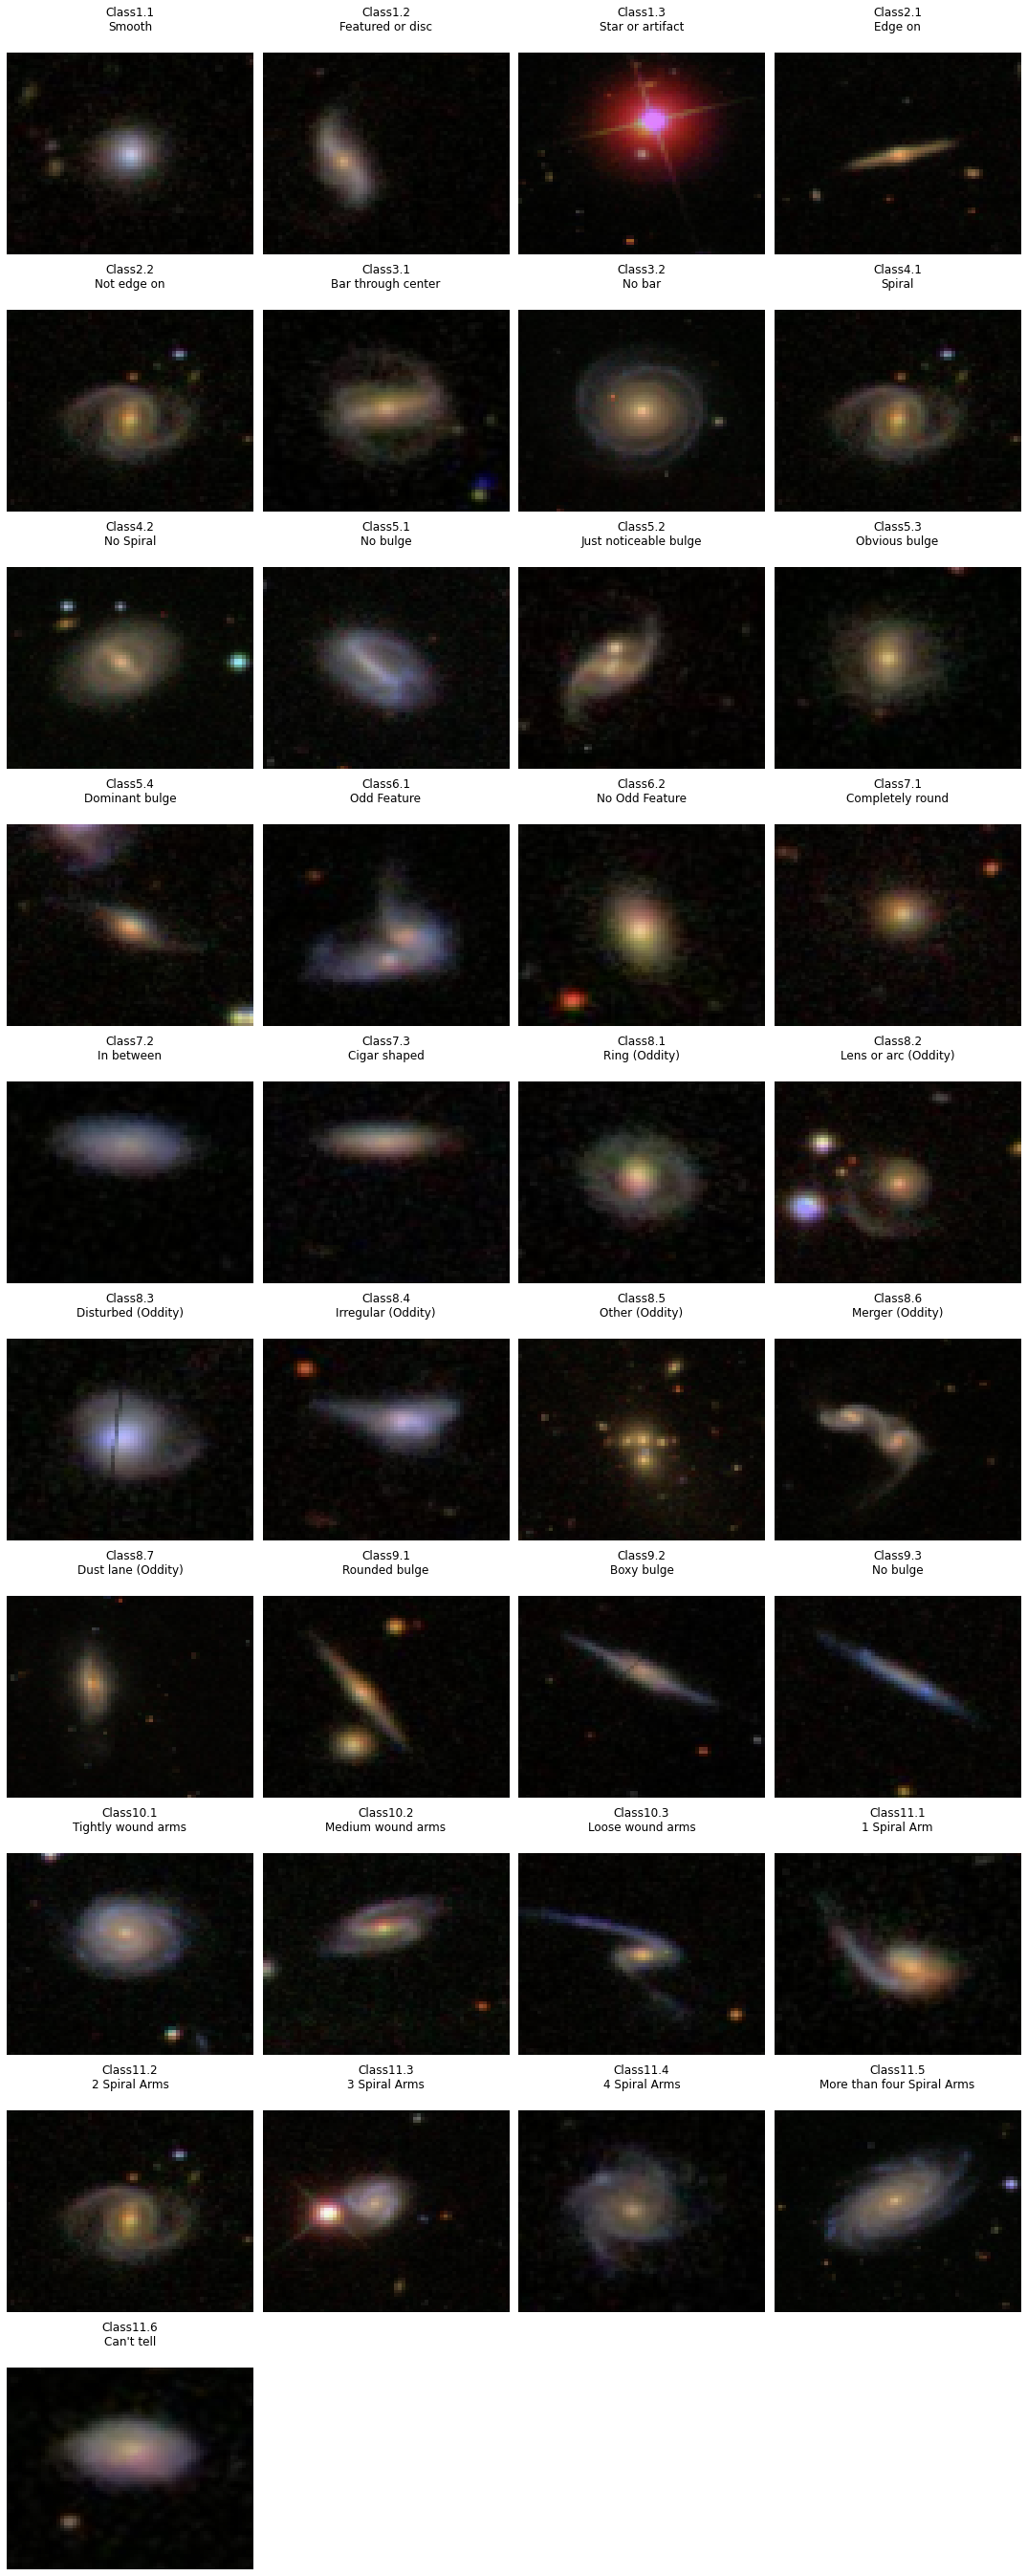
<p>Next, I took a look at what these images actually look like. I selected the image with the highest confidence level for each class and drew them with Pyplot.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/galaxy-zoo/all-classes.png" width="95%" />
  <br />
    <em>Figure 3: The image with the maximum confidence level for each class in the dataset. </em>
</p>

<p>Super cool! I never get bored of looking at pictures like this.</p>

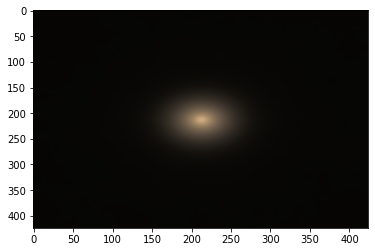
<p>I have two main takeaways here: First, it appears as though the galaxies tend to be centered in the image. And second, like space itself, the majority of each image tends to be empty black space. To test this hypothesis, I took the average of all images.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/galaxy-zoo/average.png" width="95%" />
  <br />
    <em>Figure 4: The average of all 61,578 images in the dataset. </em>
</p>

<p>The hypothesis appears correct. Because of this, I’m going to preprocess the images by extracting the region of interest to get the biggest bang for my buck in the convolution layers of my neural network.</p>

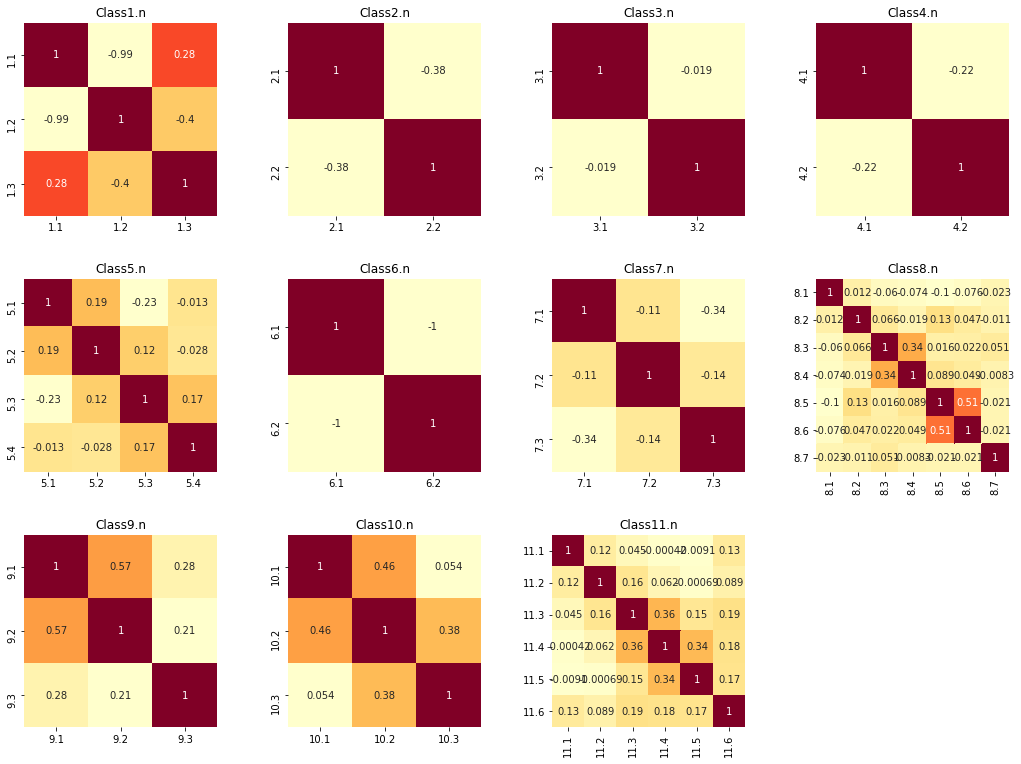
<p>I was also curious to see how strongly the crowd-sourced participants agreed with each other. Because we don’t have a single source of truth, we’re not really modeling which galaxies have which attributes but rather how confident the human scorers that a galaxy has a certain attribute.</p>

<p>To understand this better, I drew correlation matrices for the answers to each question as heatmaps.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/galaxy-zoo/corr-ind.png" width="95%" />
  <br />
    <em>Figure 5: Correlation matrices for each of the eleven questions. </em>
</p>

<p>If the participants were mostly in agreement for a particular question, there will be very little correlation between the answers to each question. However if there is disagreement, then there will be a higher level of correlation.</p>

<p>This is important because because we’re modeling people’s decision-making process, and if they aren’t confident than it might be a challenge for our model to be confident.</p>

<h2 id="benchmarking">Benchmarking</h2>

<p>Though this is a heart a classification problem, the objective of modeling the confidence level of humans classifying the galaxies transforms it into a regression problem.</p>

<p>As mentioned above, I’m going to be using an element-wise root mean-squared-error (RMSE) scoring function. Unlike classification problems where things like confusion matrices, precision, recall, and F1 scores are easy to understand, RMSE is a bit more abstract. You can’t really say what a ‘good’ RMSE score is, rather you have to set a baseline benchmark for the minimum possible performance and improve from there.</p>

<p>On the Kaggle leaderboard there is a “central pixel benchmark” of 0.16194. This is found by predicting the classes simply based on the average scores for images with the same central pixel. It seems like a decent score fall somewhere between 0.10 and 0.12 with the winner achieving 0.07941. With my time constraint of just a week for the project I don’t think I’m going to hit the winning score, but I’d be happy falling comfortably within the top half of scores.</p>

<p>But since this is a learning exercise, I decided to make my own benchmark. I chose three strategies:</p>

<ul>
  <li>Linear regression based on the central pixels</li>
  <li>Linear regression based on the average pixels</li>
  <li>A sanity check of just the average confidence to see if the previous two have any meaning</li>
</ul>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">average_color</span><span class="p">(</span><span class="n">pic</span><span class="p">):</span>
    <span class="k">return</span> <span class="n">np</span><span class="p">.</span><span class="nb">sum</span><span class="p">(</span><span class="n">pic</span><span class="p">,</span> <span class="n">axis</span><span class="o">=</span><span class="p">(</span><span class="mi">1</span><span class="p">,</span><span class="mi">2</span><span class="p">))</span> <span class="o">/</span> <span class="p">(</span><span class="n">pic</span><span class="p">.</span><span class="n">shape</span><span class="p">[</span><span class="mi">1</span><span class="p">]</span> <span class="o">*</span> <span class="n">pic</span><span class="p">.</span><span class="n">shape</span><span class="p">[</span><span class="mi">2</span><span class="p">])</span>

<span class="k">def</span> <span class="nf">center_pixel</span><span class="p">(</span><span class="n">pic</span><span class="p">):</span>
    <span class="k">return</span> <span class="n">pic</span><span class="p">[:,</span><span class="nb">int</span><span class="p">(</span><span class="n">pic</span><span class="p">.</span><span class="n">shape</span><span class="p">[</span><span class="mi">1</span><span class="p">]</span> <span class="o">/</span> <span class="mi">2</span><span class="p">),</span><span class="nb">int</span><span class="p">(</span><span class="n">pic</span><span class="p">.</span><span class="n">shape</span><span class="p">[</span><span class="mi">2</span><span class="p">]</span> <span class="o">/</span> <span class="mi">2</span><span class="p">),:]</span>

<span class="n">lr</span> <span class="o">=</span> <span class="n">sklearn</span><span class="p">.</span><span class="n">linear_model</span><span class="p">.</span><span class="n">LinearRegression</span><span class="p">()</span>
<span class="n">lr</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">X_train</span><span class="p">,</span> <span class="n">y_train</span><span class="p">)</span>
<span class="n">pred</span> <span class="o">=</span> <span class="n">lr</span><span class="p">.</span><span class="n">predict</span><span class="p">(</span><span class="n">X_test</span><span class="p">)</span>
</code></pre></div></div>
<p>The results?</p>

<ul>
  <li>Central Pixel RMSE: 0.1564</li>
  <li>Average Pixel RMSE: 0.1599</li>
</ul>

<p>Both are better than the provided benchmark! But does this mean anything?</p>

<ul>
  <li>Just the Average Confidence RMSE: 0.1639</li>
</ul>

<p>Linear regression only beat just using the class average for every image by about 4.6%. Looks like we’ll have to use deep learning after all!</p>

<h2 id="preprocessing">Preprocessing</h2>

<p>The problem with these images is that they have a lot of empty black space, and as I’m building a computationally intense neural network I really don’t want to have billions of operations analyzing nothing. My strategy was to find the region on interest from each image and crop it with a 20% pad on each side and then save as a 64x64 pixel PNG. I did this by analyzing all of the contours of luminescence in the image, bounding them with a rectangle, and then finding the biggest rectangle. The result was a much tighter crop, and as a happy side effect it introduced some variance to the position of the center pixel.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">DATA</span> <span class="o">=</span> <span class="s">'source files'</span>
<span class="n">DIR_64</span> <span class="o">=</span> <span class="s">'output for 64x64 images'</span>

<span class="n">padding_size</span> <span class="o">=</span> <span class="mf">0.2</span>

<span class="k">for</span> <span class="n">image</span> <span class="ow">in</span> <span class="n">labels</span><span class="p">.</span><span class="n">GalaxyID</span><span class="p">:</span>

    <span class="n">im</span> <span class="o">=</span> <span class="n">cv2</span><span class="p">.</span><span class="n">imread</span><span class="p">(</span><span class="n">DATA</span> <span class="o">+</span> <span class="n">image</span><span class="p">)</span>
    <span class="n">im2</span> <span class="o">=</span> <span class="n">cv2</span><span class="p">.</span><span class="n">cvtColor</span><span class="p">(</span><span class="n">im</span><span class="p">,</span> <span class="n">cv2</span><span class="p">.</span><span class="n">COLOR_RGB2GRAY</span><span class="p">)</span>
    <span class="n">ret</span><span class="p">,</span> <span class="n">thresh</span> <span class="o">=</span> <span class="n">cv2</span><span class="p">.</span><span class="n">threshold</span><span class="p">(</span><span class="n">im2</span><span class="p">,</span> <span class="mi">10</span><span class="p">,</span> <span class="mi">255</span><span class="p">,</span> <span class="mi">0</span><span class="p">)</span>
    <span class="n">contours</span><span class="p">,</span> <span class="n">hierarchy</span> <span class="o">=</span> <span class="n">cv2</span><span class="p">.</span><span class="n">findContours</span><span class="p">(</span><span class="n">thresh</span><span class="p">,</span> <span class="n">cv2</span><span class="p">.</span><span class="n">RETR_LIST</span><span class="p">,</span> <span class="n">cv2</span><span class="p">.</span><span class="n">CHAIN_APPROX_SIMPLE</span><span class="p">)</span>

    <span class="n">ROI</span> <span class="o">=</span> <span class="p">(</span><span class="mi">0</span><span class="p">,</span><span class="mi">0</span><span class="p">,</span><span class="mi">0</span><span class="p">,</span><span class="mi">0</span><span class="p">)</span> <span class="c1"># Region of interest
</span>    <span class="n">ROI_area</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="k">for</span> <span class="n">contour</span> <span class="ow">in</span> <span class="n">contours</span><span class="p">:</span> <span class="c1"># cv.RETR_LIST exports contours as a list.
</span>        <span class="n">x</span><span class="p">,</span> <span class="n">y</span><span class="p">,</span> <span class="n">width</span><span class="p">,</span> <span class="n">height</span> <span class="o">=</span> <span class="n">cv2</span><span class="p">.</span><span class="n">boundingRect</span><span class="p">(</span><span class="n">contour</span><span class="p">)</span>
        <span class="n">area</span> <span class="o">=</span> <span class="n">width</span> <span class="o">*</span> <span class="n">height</span>
        <span class="k">if</span> <span class="n">area</span> <span class="o">&gt;</span> <span class="n">ROI_area</span><span class="p">:</span>
            <span class="n">ROI_area</span> <span class="o">=</span> <span class="n">area</span>
            <span class="n">ROI</span> <span class="o">=</span> <span class="p">(</span><span class="n">x</span><span class="p">,</span><span class="n">y</span><span class="p">,</span><span class="n">width</span><span class="p">,</span><span class="n">height</span><span class="p">)</span>

    <span class="n">x</span><span class="p">,</span> <span class="n">y</span><span class="p">,</span> <span class="n">width</span><span class="p">,</span> <span class="n">height</span> <span class="o">=</span> <span class="n">ROI</span>

    <span class="k">if</span> <span class="n">width</span> <span class="o">&gt;</span> <span class="n">height</span><span class="p">:</span>
        <span class="n">pad</span> <span class="o">=</span> <span class="nb">int</span><span class="p">(</span><span class="n">width</span> <span class="o">*</span> <span class="n">padding_size</span><span class="p">)</span>
    <span class="k">else</span><span class="p">:</span>
        <span class="n">pad</span> <span class="o">=</span> <span class="nb">int</span><span class="p">(</span><span class="n">height</span> <span class="o">*</span> <span class="n">padding_size</span><span class="p">)</span>

    <span class="k">if</span> <span class="p">(</span><span class="n">y</span><span class="o">-</span><span class="n">pad</span> <span class="o">&gt;=</span> <span class="mi">0</span> <span class="ow">and</span>
        <span class="n">x</span><span class="o">-</span><span class="n">pad</span> <span class="o">&gt;=</span> <span class="mi">0</span> <span class="ow">and</span>
        <span class="n">y</span> <span class="o">+</span> <span class="nb">max</span><span class="p">(</span><span class="n">width</span><span class="p">,</span> <span class="n">height</span><span class="p">)</span> <span class="o">+</span> <span class="n">pad</span> <span class="o">&lt;</span> <span class="n">im</span><span class="p">.</span><span class="n">shape</span><span class="p">[</span><span class="mi">1</span><span class="p">]</span> <span class="ow">and</span>
        <span class="n">x</span> <span class="o">+</span> <span class="nb">max</span><span class="p">(</span><span class="n">width</span><span class="p">,</span> <span class="n">height</span><span class="p">)</span> <span class="o">+</span> <span class="n">pad</span> <span class="o">&lt;</span> <span class="n">im</span><span class="p">.</span><span class="n">shape</span><span class="p">[</span><span class="mi">0</span><span class="p">]):</span>
        <span class="n">crop</span> <span class="o">=</span> <span class="n">im</span><span class="p">[</span><span class="n">y</span><span class="o">-</span><span class="n">pad</span><span class="p">:</span><span class="n">y</span><span class="o">+</span><span class="nb">max</span><span class="p">(</span><span class="n">width</span><span class="p">,</span><span class="n">height</span><span class="p">)</span><span class="o">+</span><span class="n">pad</span><span class="p">,</span><span class="n">x</span><span class="o">-</span><span class="n">pad</span><span class="p">:</span><span class="n">x</span><span class="o">+</span><span class="nb">max</span><span class="p">(</span><span class="n">width</span><span class="p">,</span><span class="n">height</span><span class="p">)</span><span class="o">+</span><span class="n">pad</span><span class="p">]</span>
    <span class="k">else</span><span class="p">:</span>
        <span class="n">crop</span> <span class="o">=</span> <span class="n">im</span>

    <span class="n">image</span> <span class="o">=</span> <span class="n">image</span><span class="p">.</span><span class="n">replace</span><span class="p">(</span><span class="s">'jpg'</span><span class="p">,</span><span class="s">'png'</span><span class="p">)</span> <span class="c1"># I don't want to multiply the compression loss. meme.jpg.jpg.jpg
</span>
    <span class="n">cv2</span><span class="p">.</span><span class="n">imwrite</span><span class="p">(</span>
        <span class="n">DIR_64_WIDE</span> <span class="o">+</span> <span class="n">image</span><span class="p">,</span>
        <span class="n">cv2</span><span class="p">.</span><span class="n">resize</span><span class="p">(</span><span class="n">crop</span><span class="p">,</span> <span class="p">(</span><span class="mi">64</span><span class="p">,</span><span class="mi">64</span><span class="p">),</span> <span class="n">interpolation</span><span class="o">=</span><span class="n">cv2</span><span class="p">.</span><span class="n">INTER_AREA</span><span class="p">)</span>
    <span class="p">)</span>
</code></pre></div></div>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/galaxy-zoo/roi-color.png" width="95%" />
  <br />
    <em>Figure 6: Images with the maximum confidence level from each class cropped around the region of interest. </em>
</p>

<h2 id="convolutional-neural-network">Convolutional Neural Network</h2>

<p>I’m going to use a convolutional neural network (CNN) for this problem. CNNs are uniquely suited for image classification problems because they can explore local relationships between pixels rather than looking at the whole picture all at once. I’ll explain more about that below.</p>

<p>In PyTorch, a neural network is defined as a class where each layer is a parameter initialized by a constructor with a forward propagation method. Input data is propagated forward through the network to make a prediction. Then it is evaluated by an error function, and the error is back-propagated through the network to update the weights.</p>

<p><strong>Neurons</strong></p>

<p>A neural network is composed of layers of neurons, which are a simple linear equation wrapped in an activation function. The output of each neuron is connected to one or more neurons in the subsequent layers depending on the architecture of the network.</p>

<p>$z = wx + b$   &lt;- The linear equation</p>

<p>Where:</p>
<ul>
  <li>$z$ = output</li>
  <li>$w$ = weight</li>
  <li>$x$ = input</li>
  <li>$b$ = bias</li>
</ul>

<p>This information is stored in tensors (where the popular library TensorFlow got its name), which are often implemented as multidimensional arrays. In PyTorch, the tensor interface is modeled after the Numpy interface. A neuron has individual $w$ and $b$ values for each connection to another neuron in subsequent layers. A neural network is composed of many of these tensors connected in layers or as a graph. In the case of a convolution layer, there is a many to one relationship where outputs of neurons in a local area feed into a single neuron in the next layer. In a densely connected layer, or fully connected layer, each neuron is connected to every neuron in the subsequent layer.</p>

<p>That is the basic idea behind an Artificial Neural Network (ANN) or multilayer perceptron, and other architectures build off of this with different types of layers and structures between layers.</p>

<p><strong>Activation Functions</strong></p>

<p>Why can’t we just use the linear equation for neurons? The goal of a neural network is to create a non-linear decision boundary, it’s basically a non-linear function approximator. But there’s an interesting property of linear functions: the composition of two linear functions is always a linear function. If we were to use a linear activation function, no matter how many layers we create in the network the final result will always result in a linear function $w’x + b’$. We end up with a more computationally expensive linear regression model that consolidates a large number of features.</p>

<p>That’s neither interesting or useful when we’re classifying an image. We need something that explores complex relationships not only between the input features (pixels), but between the layers upon layers of these neurons. Remember that the task we’re trying to solve is approximating the process that happens in the human eye and brain between looking at a picture of a galaxy and clicking the answer to a question about that galaxy. To accomplish non-linearity, need to wrap our linear equation in an activation function that breaks linearity.</p>

<p>The most popular activation function for problems like this is a Rectified Linear Unit, or ReLU. This is extraordinarily simple:</p>

<p>$\sigma(x) = max(x,0)$</p>

<p>If the output is greater than zero, we simply use the output of the linear equation. If not, we use zero. Despite being simple, this is the most effective activation function for breaking linearity in a regression problem. It does have a few pitfalls, one being that a neuron can “die” or effectively be zero for any state. This can be solved with a Leaky ReLU, or replacing zero with a tiny multiple of x like this:</p>

<p>$\sigma(x) = max(x,0.005x)$</p>

<p>This isn’t a one-size-fits-all solution. For regression problems where our target is a probability, like this one, we can use a sigmoid function. This is guaranteed to output a number between 0 and 1.</p>

<p>$\sigma(x)= \frac{1}{1+e^{-z}}$</p>

<p><strong>Convolution Layers</strong></p>

<p>Convolution layers composed of kernels, or <a href="https://en.wikipedia.org/wiki/Kernel_(image_processing)">image filters</a>. Filters pass over an image in steps, creating a new image where each pixel is the convolution of the filter matrix and a subsection of the image. Convolution is a matrix operation denoted by an asterisk $*$ that is in essence a weighted combination of two matrices.
It passes in overlapping steps, and the output matrices lose a couple pixels based on the size of the kernel (one pixel on each edge for a 3x3 kernel) unless padding is applied.</p>

<p>These kernels allow the network to analyze local relationships between pixels rather than looking at the entire image.</p>

<p>One typical filter is a sharpening filter, in 3x3 form here, where n is the level of sharpening to be applied.</p>

<p>  0   -1   0</p>

<p>  -1   n   -1</p>

<p>  0   -1   0</p>

<p>Anyone familiar with image processing will recognize this kernel. But what makes a CNN powerful is that the convolution layers built from neurons will in effect learn new filters that are uniquely fitted to identifying and understanding features in the images. It will likely learn an edge detection filter and other standard filters, but it will also learn unique filters that pick up on subtle things.</p>

<p>The tensor in a convolution layer can contain multiple kernels. In effect, when we forward propagate through a convolution layer we’re creating one new matrix for each kernel.</p>

<p><strong>Pooling</strong></p>

<p>When we filter an input matrix through these feature maps, we retain the same dimensionality. But the real power of a convolutional neural network comes from extracting features from an original input image using feature maps, and then extracting subsequently more abstract features from combinations of the outputs.</p>

<p>After each convolution layer, we are increasing the width of our network, that is the number of filtered images. As we add on layers, we begin to suffer from the curse of dimensionality and the number of neurons explodes. It becomes extremely computationally expensive, and carrying that extra data hurts more than helps.</p>

<p>Because our objective with the learned kernels is to recognize patterns, reducing the size of the matrices effectively allows the neural network to zoom out and look at relationships between features recognized at previous convolution steps.</p>

<p>Remember that our ultimate goal is to understand the relationship between the pixels in an image and ultimately turn that information into 37 answers to 11 questions. Imagine looking very close at a picure of a car. Looking through a magnifying glass, you can recognize where edges and smooth surfaces are. Put down the magnifying glass and you can see where those edges make a car company logo, a unique headlight shape, a certain type of wheel. Step away from the photo and you can see the whole car made up of these components. You don’t need to see the pixels that define the boundary between the headlight and the hood to understand that the collection of parts you are looking at make either a Toyota or a BMW.</p>

<p>The theory behind a CNN is the same. As information flows through the network, higher level features are being extracted and it’s important to recognize a wider variety of features without getting bogged down in tiny details.</p>

<p>Pooling layers reduce the size our our matrices by breaking them down into grids, say 4x4, and reducing them each to a single pixes. There are many strategies, like max, sum, average, etc, and each have their strenghts and benefits.</p>

<p>Max performs kind of like a sharpening filter, and with our grayscale input images I think it will help our network pull out the most important features.</p>

<p><strong>Fully Connected</strong></p>

<p>Fully connected layers are flat layers with a full connection to every neuron in the previous and subsequent layers. Where the convolution layers explore local relationships, the fully connected layers begin to look at the whole picture. These layers are basically act as a non-linear function approximator.</p>

<p>The first fully connected layer takes the features detected by the convolution layers as input and the final fully connected layer outputs our prediction.</p>

<p><strong>Regularization</strong></p>

<p>The dense connections in this part of the network are great at analyzing the relationships between features in an image and whatever we are trying to predict, but they do come with a downside. Sometimes they just memorize data and perform amazing on the training data set, but not so well on testing data.</p>

<p>Similar to how the Boston Dynamics robots learn to be more stable on their feet from employees kicking them down, the neural network becomes stronger when we disrupt it by shutting off neurons at random. This causes other neurons which may otherwise not be used for a particular decision to pick up the slack and find alternate ways of making that decision. This is a very common regularization strategy in deep learning.</p>

<p>Another regularization strategy is <a href="https://en.wikipedia.org/wiki/Batch_normalization">batch normalization</a>. This is one of those funny things that works even though people are totally sure <em>why</em> it works. This is a PHD level topic, but my basic understanding is that it prevents major shifts in input data from having an outsized effect on the weights and balances. The step of updating the network parameters is called <a href="https://en.wikipedia.org/wiki/Backpropagation">back propagation</a>, where the hill we’re descending is a gradient of the loss function with respect to the weights. Batch normalization smooths out this gradient and prevents dramatic changes. The slower and more stable learning process is able to find solutions faster because you don’t have to waste steps correcting overshoots and major shifts in the weights.</p>

<h2 id="building-the-model">Building the Model</h2>

<p><strong>Batch Generator</strong></p>

<p>I’m working with limited RAM here, so it is necessary for me batch the data. I wrote a custom batch generator to accomplish this. While I did the major preprocessing beforehand and saved the data to storage, I reserved the faster preprocessing step of randomly rotating images for the batch generator to save on storage space.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">torch_batches</span><span class="p">(</span><span class="n">pics</span><span class="p">,</span> <span class="n">labels</span><span class="p">,</span> <span class="n">path</span><span class="o">=</span><span class="n">DATA</span><span class="p">,</span> <span class="n">batch_size</span><span class="o">=</span><span class="mi">30</span><span class="p">,</span> <span class="n">rotate</span><span class="o">=</span><span class="bp">False</span><span class="p">,</span> <span class="n">fmt</span><span class="o">=</span><span class="s">'png'</span><span class="p">):</span>
    <span class="s">'''
    Generate batches of PyTorch tensors from a list of image filenames.
    DATA is a global variable with the path to the image folder.  
    '''</span>
    <span class="n">angles</span> <span class="o">=</span> <span class="n">np</span><span class="p">.</span><span class="n">array</span><span class="p">([</span><span class="mi">0</span><span class="p">,</span><span class="mi">90</span><span class="p">,</span><span class="mi">180</span><span class="p">,</span><span class="mi">270</span><span class="p">])</span>
    <span class="n">labels</span> <span class="o">=</span> <span class="n">torch</span><span class="p">.</span><span class="n">tensor</span><span class="p">(</span><span class="n">labels</span><span class="p">,</span> <span class="n">dtype</span><span class="o">=</span><span class="n">torch</span><span class="p">.</span><span class="n">float32</span><span class="p">)</span>
    <span class="n">l</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">pics</span><span class="p">)</span>
    <span class="n">batches</span> <span class="o">=</span> <span class="nb">int</span><span class="p">(</span><span class="n">l</span><span class="o">/</span><span class="n">batch_size</span><span class="p">)</span>
    <span class="n">leftover</span> <span class="o">=</span> <span class="n">l</span> <span class="o">%</span> <span class="n">batch_size</span>
    <span class="k">for</span> <span class="n">batch</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">batches</span><span class="p">):</span>
        <span class="n">start</span> <span class="o">=</span> <span class="n">batch</span> <span class="o">*</span> <span class="n">batch_size</span>
        <span class="n">this_batch</span> <span class="o">=</span> <span class="n">pics</span><span class="p">[</span><span class="n">start</span><span class="p">:</span><span class="n">start</span><span class="o">+</span><span class="n">batch_size</span><span class="p">]</span>
        <span class="n">batch_labels</span> <span class="o">=</span> <span class="n">labels</span><span class="p">[</span><span class="n">start</span><span class="p">:</span><span class="n">start</span><span class="o">+</span><span class="n">batch_size</span><span class="p">,:]</span>

        <span class="k">if</span> <span class="n">rotate</span><span class="p">:</span>
            <span class="k">yield</span> <span class="n">torch</span><span class="p">.</span><span class="n">tensor</span><span class="p">([</span><span class="n">scipy</span><span class="p">.</span><span class="n">ndimage</span><span class="p">.</span><span class="n">rotate</span><span class="p">(</span>
                                <span class="n">plt</span><span class="p">.</span><span class="n">imread</span><span class="p">(</span><span class="n">path</span> <span class="o">+</span> <span class="n">pic</span><span class="p">,</span> <span class="nb">format</span><span class="o">=</span><span class="n">fmt</span><span class="p">),</span>
                                <span class="n">reshape</span><span class="o">=</span><span class="bp">False</span><span class="p">,</span>
                                <span class="n">angle</span><span class="o">=</span><span class="n">np</span><span class="p">.</span><span class="n">random</span><span class="p">.</span><span class="n">randint</span><span class="p">(</span><span class="mi">0</span><span class="p">,</span><span class="mi">360</span><span class="p">)</span>
                                <span class="p">)</span>
                            <span class="k">for</span> <span class="n">pic</span> <span class="ow">in</span> <span class="n">this_batch</span><span class="p">],</span> <span class="n">dtype</span><span class="o">=</span><span class="n">torch</span><span class="p">.</span><span class="n">float32</span><span class="p">).</span><span class="n">permute</span><span class="p">(</span><span class="mi">0</span><span class="p">,</span> <span class="mi">3</span><span class="p">,</span> <span class="mi">1</span><span class="p">,</span> <span class="mi">2</span><span class="p">),</span> <span class="n">batch_labels</span><span class="p">,</span> <span class="n">this_batch</span>
        <span class="k">else</span><span class="p">:</span>
            <span class="k">yield</span> <span class="n">torch</span><span class="p">.</span><span class="n">tensor</span><span class="p">([</span> <span class="n">plt</span><span class="p">.</span><span class="n">imread</span><span class="p">(</span><span class="n">path</span> <span class="o">+</span> <span class="n">pic</span><span class="p">,</span> <span class="nb">format</span><span class="o">=</span><span class="n">fmt</span><span class="p">)</span> <span class="k">for</span> <span class="n">pic</span> <span class="ow">in</span> <span class="n">this_batch</span><span class="p">],</span> <span class="n">dtype</span><span class="o">=</span><span class="n">torch</span><span class="p">.</span><span class="n">float32</span><span class="p">).</span><span class="n">permute</span><span class="p">(</span><span class="mi">0</span><span class="p">,</span> <span class="mi">3</span><span class="p">,</span> <span class="mi">1</span><span class="p">,</span> <span class="mi">2</span><span class="p">),</span> <span class="n">batch_labels</span><span class="p">,</span> <span class="n">this_batch</span>
</code></pre></div></div>

<p><strong>Defining the CNN</strong></p>

<p>PyTorch is a low-level deep learning library (it does a lot of other things to, it’s basically a GPU accelerated Numpy with machine learning and statistics modules that replaces matrices with tensors), meaning that it does not automatically build the structure of your neural network like a higher-level library like Keras would. This is a challenge because you have to be accurate in calculating the shape of your data as it flows through the network.</p>

<p>The get_output_width() function and definition of the variables above the Net() class definition made this much easier and allowed me to make adjustments and experiment more easily.</p>

<p>The network consists of five layers:</p>
<ul>
  <li>Convolution with 3 channels in and 64 filters. ReLU activation.</li>
  <li>Covolution with 96 filters and batch normalization. ReLU activation.
    <ul>
      <li>flatten non-index dimensions</li>
    </ul>
  </li>
  <li>Fully connected layer with dropouts and 1/8 the number of output neurons as previous convolution layer. ReLU activation.</li>
  <li>Fully connected layer with dropouts and 1/4 the number of output neurons as previous layer. ReLU activation.</li>
  <li>Fully connected layer with 37 outputs, one for each class. Sigmoid activation.</li>
</ul>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">get_output_width</span><span class="p">(</span><span class="n">width</span><span class="p">,</span> <span class="n">kernel</span><span class="p">,</span> <span class="n">padding</span><span class="p">,</span> <span class="n">stride</span><span class="p">):</span>
    <span class="k">return</span> <span class="nb">int</span><span class="p">((</span><span class="n">width</span> <span class="o">+</span> <span class="mi">2</span> <span class="o">*</span> <span class="n">padding</span> <span class="o">-</span> <span class="n">kernel</span> <span class="o">-</span> <span class="mi">1</span><span class="p">)</span> <span class="o">/</span> <span class="n">stride</span> <span class="o">+</span> <span class="mi">1</span><span class="p">)</span>

<span class="n">classes</span> <span class="o">=</span> <span class="n">labels</span><span class="p">.</span><span class="n">columns</span><span class="p">[</span><span class="mi">1</span><span class="p">:]</span>

<span class="n">in_width</span> <span class="o">=</span> <span class="mi">64</span>

<span class="n">kernel</span> <span class="o">=</span> <span class="mi">5</span>
<span class="n">pool_kernel</span> <span class="o">=</span> <span class="mi">2</span>
<span class="n">padding</span> <span class="o">=</span> <span class="nb">int</span><span class="p">(</span><span class="n">kernel</span><span class="o">/</span><span class="mi">2</span><span class="p">)</span>
<span class="n">stride</span> <span class="o">=</span> <span class="mi">1</span>

<span class="n">c1_in</span> <span class="o">=</span> <span class="mi">3</span>
<span class="n">c1_kernel</span> <span class="o">=</span> <span class="mi">9</span>
<span class="n">c1_out</span> <span class="o">=</span> <span class="mi">64</span>
<span class="n">c1_conv_width</span> <span class="o">=</span> <span class="n">get_output_width</span><span class="p">(</span><span class="n">in_width</span><span class="p">,</span> <span class="n">c1_kernel</span><span class="p">,</span> <span class="nb">int</span><span class="p">(</span><span class="n">c1_kernel</span><span class="o">/</span><span class="mi">2</span><span class="p">),</span> <span class="n">stride</span><span class="p">)</span>
<span class="n">c1_pooled_width</span> <span class="o">=</span> <span class="n">get_output_width</span><span class="p">(</span><span class="n">c1_conv_width</span><span class="p">,</span> <span class="nb">int</span><span class="p">(</span><span class="n">pool_kernel</span><span class="o">/</span><span class="mi">2</span><span class="p">),</span> <span class="mi">0</span><span class="p">,</span> <span class="n">pool_kernel</span><span class="p">)</span>

<span class="n">c2_kernel</span> <span class="o">=</span> <span class="mi">5</span>
<span class="n">c2_out</span> <span class="o">=</span> <span class="mi">96</span>
<span class="n">c2_conv_width</span> <span class="o">=</span> <span class="n">get_output_width</span><span class="p">(</span><span class="n">c1_pooled_width</span><span class="p">,</span> <span class="n">c2_kernel</span><span class="p">,</span> <span class="nb">int</span><span class="p">(</span><span class="n">c2_kernel</span><span class="o">/</span><span class="mi">2</span><span class="p">),</span> <span class="n">stride</span><span class="p">)</span>
<span class="n">c2_pooled_width</span> <span class="o">=</span> <span class="n">get_output_width</span><span class="p">(</span><span class="n">c2_conv_width</span><span class="p">,</span> <span class="n">pool_kernel</span><span class="p">,</span> <span class="nb">int</span><span class="p">(</span><span class="n">pool_kernel</span><span class="o">/</span><span class="mi">2</span><span class="p">),</span> <span class="n">pool_kernel</span><span class="p">)</span>

<span class="n">full_1_in</span> <span class="o">=</span> <span class="n">c2_out</span> <span class="o">*</span> <span class="n">c2_pooled_width</span> <span class="o">*</span> <span class="n">c2_pooled_width</span>
<span class="n">full_1_out</span> <span class="o">=</span> <span class="nb">int</span><span class="p">(</span><span class="n">full_1_in</span> <span class="o">/</span> <span class="mi">8</span><span class="p">)</span>
<span class="n">full_2_out</span> <span class="o">=</span> <span class="nb">int</span><span class="p">(</span><span class="n">full_1_out</span><span class="o">/</span><span class="mi">4</span><span class="p">)</span>
<span class="n">full_3_out</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">classes</span><span class="p">)</span>


<span class="k">class</span> <span class="nc">Net</span><span class="p">(</span><span class="n">nn</span><span class="p">.</span><span class="n">Module</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="nb">super</span><span class="p">(</span><span class="n">Net</span><span class="p">,</span> <span class="bp">self</span><span class="p">).</span><span class="n">__init__</span><span class="p">()</span>
        <span class="s">'''
        These are the layers in the network, and their attributes are the
        weights and biases of the neurons.
        '''</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">conv1</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Conv2d</span><span class="p">(</span><span class="n">in_channels</span><span class="o">=</span><span class="n">c1_in</span><span class="p">,</span>
                               <span class="n">out_channels</span><span class="o">=</span><span class="n">c1_out</span><span class="p">,</span>
                               <span class="n">kernel_size</span><span class="o">=</span><span class="n">c1_kernel</span><span class="p">,</span>
                               <span class="n">stride</span><span class="o">=</span><span class="n">stride</span><span class="p">,</span>
                               <span class="n">padding</span><span class="o">=</span><span class="n">padding</span><span class="p">,</span>
                               <span class="n">padding_mode</span><span class="o">=</span><span class="s">'zeros'</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">pool</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">MaxPool2d</span><span class="p">(</span><span class="n">pool_kernel</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">conv2</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Conv2d</span><span class="p">(</span><span class="n">in_channels</span><span class="o">=</span><span class="n">c1_out</span><span class="p">,</span>
                               <span class="n">out_channels</span><span class="o">=</span><span class="n">c2_out</span><span class="p">,</span>
                               <span class="n">kernel_size</span><span class="o">=</span><span class="n">c2_kernel</span><span class="p">,</span>
                               <span class="n">stride</span><span class="o">=</span><span class="n">stride</span><span class="p">,</span>
                               <span class="n">padding</span><span class="o">=</span><span class="n">padding</span><span class="p">,</span>
                               <span class="n">padding_mode</span><span class="o">=</span><span class="s">'zeros'</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">conv2_bn</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">BatchNorm2d</span><span class="p">(</span><span class="n">c2_out</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">fc1</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Linear</span><span class="p">(</span><span class="n">full_1_in</span><span class="p">,</span> <span class="n">full_1_out</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">fc2</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Linear</span><span class="p">(</span><span class="n">full_1_out</span><span class="p">,</span> <span class="n">full_2_out</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">fc3</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Linear</span><span class="p">(</span><span class="n">full_2_out</span><span class="p">,</span> <span class="n">full_3_out</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">dropout</span> <span class="o">=</span> <span class="n">nn</span><span class="p">.</span><span class="n">Dropout</span><span class="p">(</span><span class="n">p</span><span class="o">=</span><span class="mf">0.15</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">forward</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">x</span><span class="p">):</span>
        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">pool</span><span class="p">(</span><span class="n">F</span><span class="p">.</span><span class="n">relu</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">conv1</span><span class="p">(</span><span class="n">x</span><span class="p">)))</span>
        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">pool</span><span class="p">(</span><span class="n">F</span><span class="p">.</span><span class="n">relu</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">conv2_bn</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">conv2</span><span class="p">(</span><span class="n">x</span><span class="p">))))</span>
        <span class="n">x</span> <span class="o">=</span> <span class="n">x</span><span class="p">.</span><span class="n">view</span><span class="p">(</span><span class="n">x</span><span class="p">.</span><span class="n">size</span><span class="p">()[</span><span class="mi">0</span><span class="p">],</span><span class="o">-</span><span class="mi">1</span><span class="p">)</span>
        <span class="n">x</span> <span class="o">=</span> <span class="n">F</span><span class="p">.</span><span class="n">relu</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">dropout</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">fc1</span><span class="p">(</span><span class="n">x</span><span class="p">)))</span>
        <span class="n">x</span> <span class="o">=</span> <span class="n">F</span><span class="p">.</span><span class="n">relu</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">dropout</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">fc2</span><span class="p">(</span><span class="n">x</span><span class="p">)))</span>
        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">fc3</span><span class="p">(</span><span class="n">x</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">x</span>

<span class="n">net</span> <span class="o">=</span> <span class="n">Net</span><span class="p">()</span>

</code></pre></div></div>

<p><strong>Training the CNN</strong></p>

<p>I trained the CNN with the Adam optimizer. It’s a little faster than stochastic gradient descent with comparable performance. I’m loading images from storage into memory in large batches because that’s more efficient, but I’m training in smaller mini batches to prevent dramatic gradient updates. The batch size is actually a regularization strategy for neural networks.</p>

<p>I trained the model over five epochs using the ROI cropped photos with random rotation.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">optimizer</span> <span class="o">=</span> <span class="n">optim</span><span class="p">.</span><span class="n">Adam</span><span class="p">(</span><span class="n">net</span><span class="p">.</span><span class="n">parameters</span><span class="p">())</span>
<span class="n">loss_history</span> <span class="o">=</span> <span class="p">[]</span>
<span class="n">batch_size</span> <span class="o">=</span> <span class="mi">1024</span>
<span class="n">mini_batch_size</span> <span class="o">=</span> <span class="mi">64</span>

<span class="k">for</span> <span class="n">epoch</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">1</span><span class="p">,</span><span class="mi">6</span><span class="p">):</span>
    <span class="n">batch_no</span> <span class="o">=</span> <span class="mi">1</span>

    <span class="n">datagen</span> <span class="o">=</span> <span class="n">torch_batches</span><span class="p">(</span><span class="n">X_train</span><span class="p">,</span>
                        <span class="n">y_train</span><span class="p">,</span>
                        <span class="n">path</span><span class="o">=</span><span class="n">DIR_64_WIDE</span><span class="p">,</span>
                        <span class="n">batch_size</span><span class="o">=</span><span class="n">batch_size</span><span class="p">,</span>
                        <span class="n">rotate</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>

    <span class="k">for</span> <span class="n">images</span><span class="p">,</span> <span class="n">targets</span><span class="p">,</span> <span class="n">_</span> <span class="ow">in</span> <span class="n">datagen</span><span class="p">:</span> <span class="c1"># big read from storage
</span>        <span class="k">for</span> <span class="n">mini_batch</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="nb">int</span><span class="p">(</span><span class="n">batch_size</span><span class="o">/</span><span class="n">mini_batch_size</span><span class="p">)):</span>
            <span class="n">start</span> <span class="o">=</span> <span class="n">mini_batch</span><span class="o">*</span><span class="n">mini_batch_size</span>
            <span class="k">if</span> <span class="n">start</span> <span class="o">&gt;=</span> <span class="n">images</span><span class="p">.</span><span class="n">shape</span><span class="p">[</span><span class="mi">0</span><span class="p">]:</span>
                <span class="k">break</span>
            <span class="n">finish</span> <span class="o">=</span> <span class="n">start</span> <span class="o">+</span> <span class="n">mini_batch_size</span>
            <span class="n">optimizer</span><span class="p">.</span><span class="n">zero_grad</span><span class="p">()</span>   
            <span class="n">outputs</span> <span class="o">=</span> <span class="n">net</span><span class="p">(</span><span class="n">images</span><span class="p">[</span><span class="n">start</span><span class="p">:</span><span class="n">finish</span><span class="p">])</span>
            <span class="n">loss</span> <span class="o">=</span> <span class="n">weighted_mse_loss</span><span class="p">(</span><span class="n">outputs</span><span class="p">,</span> <span class="n">targets</span><span class="p">[</span><span class="n">start</span><span class="p">:</span><span class="n">finish</span><span class="p">],</span> <span class="n">loss_weight</span><span class="p">)</span>
            <span class="n">loss</span><span class="p">.</span><span class="n">backward</span><span class="p">()</span>
            <span class="n">optimizer</span><span class="p">.</span><span class="n">step</span><span class="p">()</span>
        <span class="n">batch_no</span> <span class="o">+=</span> <span class="mi">1</span>
        <span class="n">loss_history</span><span class="p">.</span><span class="n">append</span><span class="p">((</span><span class="n">epoch</span><span class="p">,</span> <span class="n">batch_no</span><span class="p">,</span> <span class="n">loss</span><span class="p">.</span><span class="n">item</span><span class="p">()))</span>
</code></pre></div></div>

<p>The result? A respectably decent score of 0.11025! I would have placed 78th in the competition.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/galaxy-zoo/loss.png" width="50%" />
  <br />
    <em>Figure 7: Weighted MSE loss over batches of 1024 images. </em>
</p>

<h2 id="closing-thoughts">Closing Thoughts</h2>

<p>I had fun working on this project. The bulk of the work was done within a week, and it was my first time using OpenCV and PyTorch. They’re both great libraries that are very approachable and easy to learn, as the Python data science community writes great documentation.</p>

<p>Given more time I would experiment more with both the preprocessing, particularly with more variance with the central pixel and maybe having the region of interest partially obscured around the edge to make the model more robust, as well as with the architecture of the neural network. I may revisit the project later on.</p>

<p>All in all, a great way to kick of my final semester’s independent study!</p>]]></content><author><name>Jay Speidell</name><email>jayspeidell@gmail.com</email></author><category term="data science" /><summary type="html"><![CDATA[This is an image classification project that I completed for my independent study at Old Dominion University. The dataset was obtained from Kaggle's Galaxy Zoo Challenge. I chose astronomy datasets for my independent study because I enjoy learning about the topic and they presented an opportunity to sharpen my deep learning and PyTorch skills.]]></summary></entry><entry><title type="html">PLAsTiCC Astronomical Classification - Light Curve Sequence Analysis</title><link href="https://jayspeidell.github.io/posts/plasticc/" rel="alternate" type="text/html" title="PLAsTiCC Astronomical Classification - Light Curve Sequence Analysis" /><published>2020-07-20T00:00:00-07:00</published><updated>2020-07-20T00:00:00-07:00</updated><id>https://jayspeidell.github.io/posts/light-curve-sequence-analysis</id><content type="html" xml:base="https://jayspeidell.github.io/posts/plasticc/"><![CDATA[<p><img src="/images/lsst/header.png" style="width:100%" /></p>

<h3 id="index">Index</h3>
<ol>
  <li><a href="#project-overview">Project Overview</a></li>
  <li><a href="#data-description">Data Description</a></li>
  <li><a href="#exploratory-data-analysis">Exploratory Data Analysis</a></li>
  <li><a href="#feature-engineering">Feature Engineering</a></li>
  <li><a href="#machine-learning">Machine Learning</a></li>
  <li><a href="#closing-thoughts">Closing Thoughts</a></li>
</ol>

<h2 id="project-overview">Project Overview</h2>

<p>This is the second project for my senior year independed study, and I chose the <a href="https://www.kaggle.com/c/PLAsTiCC-2018/" target="_blank">PLAsTiCC Astronomical Challenge</a> on Kaggle because the subject matter is fascinating and it presents an opportunity for me to practice analyzing and making predictions from time series data.</p>

<p>The data for the project is simulated data from the <a href="https://en.wikipedia.org/wiki/Vera_C._Rubin_Observatory" target="_blank">Vera C. Rubin Observatory</a> (LSST), which has a ten year mission to survey the southern sky in 2022 with a goal of classifying celestial object. The data was released in anticipation of this project to kick off the process of understanding how to transform the observed information into a labeled map of the sky.</p>

<p>I had initially tested two project approaches, time series analysis with a <a href="https://colah.github.io/posts/2015-08-Understanding-LSTMs/" target="_blank">Long Short Term Memory</a> recurrent neural network in PyTorch and <a href="https://en.wikipedia.org/wiki/Gradient_boosting" target="_blank">gradient boosted trees</a> with <a href="https://en.wikipedia.org/wiki/XGBoost" target="_blank">XGBoost</a>. I quickly determined that not only was the boosted tree model more effective, it was also much more computationally efficient.</p>

<p>This report details my process of understanding what the data represents, performing an exploratory data analysis, creating engineered features and evaluating them, and building the XGBoost model and optimizing it.</p>

<p>Unlike the Kaggle challenge for this dataset, where the goal is to ensemble many models and throw massive computational power at the problem for small incremental gains, I approached this as a business problem where the priority is speed of development, efficient training and deployment, and evaluation metrics that can be explained to a lay-person. I do think it would be fun to work alongside a subject matter expert and build an extremely high-performance ensemble model.</p>

<h2 id="data-description">Data Description</h2>

<p>The data itself consists of two CSV files. There is a metadata dataset that contains information about each object in the sky, including:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">object_is</code> - The unique ID number of each celestial object.</li>
  <li>Location (all in degrees) - This may be an important feature for land-based observations because the density of the atmosphere that light must pass through changes based on an object’s position in the sky.
    <ul>
      <li><code class="language-plaintext highlighter-rouge">ra</code>, <code class="language-plaintext highlighter-rouge">decl</code> - right ascension, declination</li>
      <li><code class="language-plaintext highlighter-rouge">gal_l</code>, <code class="language-plaintext highlighter-rouge">gal_b</code> - galactic longitude and latitude</li>
    </ul>
  </li>
  <li><code class="language-plaintext highlighter-rouge">ddf</code> - A boolean value repredenting “deep drilling field,” a more accurate observation than WFD or “wide-fast-deep”. These are the two modes of observation.</li>
  <li>Redshift - As objects move at higher speeds away from us, the doppler effect stretches out wavelengths to make the color appear more red. Due to the expansion of space, the further away from us an object is the faster it is accelerating away from us. This biases observations and must be accounted for.
    <ul>
      <li><code class="language-plaintext highlighter-rouge">hostgal_specz</code> - Redshift calculated from spectroscopic experiments. <a href="http://adsabs.harvard.edu/full/1999ASPC..191..217C" target="_blank">This is difficult from land-based telescopes,</a> but very accurate. This is very rare in the evaluation dataset, and though I will not be using that dataset I should come up with a strategy for dealing with observations where this data is not present or eliminate it entirely.</li>
      <li><code class="language-plaintext highlighter-rouge">hostgal_photoz</code> - Potometric redshift, described by the challenge as a “proxy for hostgal_specz” with lower accuracy.</li>
      <li><code class="language-plaintext highlighter-rouge">hostgal_photoz_err</code> - Error in the photometric redshift.</li>
    </ul>
  </li>
  <li><code class="language-plaintext highlighter-rouge">distmod</code> - The <a href="https://en.wikipedia.org/wiki/Absolute_magnitude" target="_blank">absolute magnitude</a> of the object, a logarithmic scale incorporating the brightness of an object and its distance. This corrects the luminosity of objects in the sky so that they can be compared as if they were all at the same difference from the observer. This feature will likely be critical as the time series data we are analyzing is the luminosity of celestial objects over time.</li>
  <li><code class="language-plaintext highlighter-rouge">mbwev</code> - Extinction of light as it passes through the milky way. The milky way contains dust that can dim light or exaggerate its redshift.</li>
  <li><code class="language-plaintext highlighter-rouge">target</code> - The target class. These are objects in a state of change, such as red drawrf stellar flares or eclipsing binary stars. They are giving off variable amounts of light, leading to the challenge of identifying objects by a time series representing luminance as a function of time.</li>
</ul>

<p>The second CSV contains the meat and potatoes of the data, the time series. There is a one-to-many relationship between the metadata and the time series data. Each row in this dataset represents one observation, and when grouped by time they represent time series for individual objects. The features are:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">object_id</code> - Matches the same variable in the metadata.</li>
  <li><code class="language-plaintext highlighter-rouge">mjd</code> - <a href="http://www.ccpo.odu.edu/~klinck/SOGLOBEC/cruise/timedate/julianday.html" target="_blank">Modified Julian Date</a>, the number of days since noon on November 17th, 1858.</li>
  <li><code class="language-plaintext highlighter-rouge">passband</code> - Optical filters that restrict the light coming through based on wavelength. Here they are integers, each representing a standard filter.</li>
  <li><code class="language-plaintext highlighter-rouge">flux</code> - The intensity of the light. As a wide field survey telescope, the LSST doesn’t capture high resolution images of tight areas but rather takes a 3 gigapixel snapshot of the sky. Instead of image recognition, the goal is to identify all objects in the night sky based on other attributes such as intensity. Unlike brightness, flux is affected by distance. In this dataset, flux is a result of image subtraction analysis.</li>
  <li><code class="language-plaintext highlighter-rouge">detected</code> - The LSST project uses image subtraction analyis, where images are subtracted from a reference template and convolved with a decorrelation kernel. This is a field of study in itself and the <a href="https://dmtn-021.lsst.io/" target="_blank">implementation writeup</a> is an interesting read, but in essence this boolean represents high variance between pixels after this process has been applied. Objects are added to this dataset if there have been a minimum of two detections, and they can represent a portion of a light curve where something interesting is happening.</li>
</ul>

<h2 id="exploratory-data-analysis">Exploratory Data Analysis</h2>

<h3 id="the-metadata">The Metadata</h3>

<p>First I want to take a look at the target classes and see how balanced they are.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/lsst/target_dist.png" width="75%" />
  <br />
    <em>Figure 1: Target class distribution. </em>
</p>

<p>There are a few classes with very low representation, which might be a big deal with this limited dataset. The most populous class, 90, has 2,313 examples, while the least populous has only 30.</p>

<p>Next I’m going to look at missing data. There is no missing data in the light curve data, but there is one feature in the metadata with nearly 30% missing: <code class="language-plaintext highlighter-rouge">distmod</code>.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">df_meta</span><span class="p">.</span><span class="n">isnull</span><span class="p">().</span><span class="nb">sum</span><span class="p">()</span><span class="o">/</span><span class="nb">len</span><span class="p">(</span><span class="n">df_meta</span><span class="p">)</span>
</code></pre></div></div>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>object_id             0.000000
ra                    0.000000
decl                  0.000000
gal_l                 0.000000
gal_b                 0.000000
ddf                   0.000000
hostgal_specz         0.000000
hostgal_photoz        0.000000
hostgal_photoz_err    0.000000
distmod               0.296254
mwebv                 0.000000
target                0.000000
</code></pre></div></div>
<p>This is a pretty big gap in the data, and it needs to be dealt with. This is the distance modulus, which corrects the luminosity of objects to make them appear from a unified frame of reference. (Keep in mind that our main feature in the light curves is flux, not luminosity, and is the result of difference analysis.) Let’s investigate to see if there are any anomalies where <code class="language-plaintext highlighter-rouge">distmod</code> is missing.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">df_meta</span><span class="p">.</span><span class="n">drop</span><span class="p">([</span><span class="s">'ra'</span><span class="p">,</span><span class="s">'decl'</span><span class="p">,</span><span class="s">'gal_l'</span><span class="p">,</span><span class="s">'gal_b'</span><span class="p">],</span> <span class="n">axis</span><span class="o">=</span><span class="mi">1</span><span class="p">)[</span><span class="n">df_meta</span><span class="p">.</span><span class="n">distmod</span><span class="p">.</span><span class="n">isnull</span><span class="p">()].</span><span class="n">sample</span><span class="p">(</span><span class="mi">10</span><span class="p">,</span> <span class="n">random_state</span><span class="o">=</span><span class="n">RANDOM</span><span class="p">).</span><span class="n">to_markdown</span><span class="p">()</span>
</code></pre></div></div>
<p>(In case you didn’t know, Pandas dataframes have a <code class="language-plaintext highlighter-rouge">to_markdown()</code> method and it’s very convenient! This entire website is built in Markdown.)</p>

<div class="table-wrapper">

  <table>
    <thead>
      <tr>
        <th style="text-align: right"> </th>
        <th style="text-align: right">object_id</th>
        <th style="text-align: right">ddf</th>
        <th style="text-align: right">hostgal_specz</th>
        <th style="text-align: right">hostgal_photoz</th>
        <th style="text-align: right">hostgal_photoz_err</th>
        <th style="text-align: right">distmod</th>
        <th style="text-align: right">mwebv</th>
        <th style="text-align: right">target</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td style="text-align: right">1947</td>
        <td style="text-align: right">315765</td>
        <td style="text-align: right">1</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.022</td>
        <td style="text-align: right">65</td>
      </tr>
      <tr>
        <td style="text-align: right">2213</td>
        <td style="text-align: right">3.47837e+06</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.01</td>
        <td style="text-align: right">16</td>
      </tr>
      <tr>
        <td style="text-align: right">5773</td>
        <td style="text-align: right">8.42242e+07</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.096</td>
        <td style="text-align: right">65</td>
      </tr>
      <tr>
        <td style="text-align: right">4641</td>
        <td style="text-align: right">5.81764e+07</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.065</td>
        <td style="text-align: right">65</td>
      </tr>
      <tr>
        <td style="text-align: right">6616</td>
        <td style="text-align: right">1.03245e+08</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.253</td>
        <td style="text-align: right">16</td>
      </tr>
      <tr>
        <td style="text-align: right">2796</td>
        <td style="text-align: right">1.58587e+07</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.021</td>
        <td style="text-align: right">16</td>
      </tr>
      <tr>
        <td style="text-align: right">3407</td>
        <td style="text-align: right">2.94167e+07</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.706</td>
        <td style="text-align: right">6</td>
      </tr>
      <tr>
        <td style="text-align: right">1913</td>
        <td style="text-align: right">310942</td>
        <td style="text-align: right">1</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.024</td>
        <td style="text-align: right">92</td>
      </tr>
      <tr>
        <td style="text-align: right">714</td>
        <td style="text-align: right">118422</td>
        <td style="text-align: right">1</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.024</td>
        <td style="text-align: right">65</td>
      </tr>
      <tr>
        <td style="text-align: right">1883</td>
        <td style="text-align: right">305673</td>
        <td style="text-align: right">1</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">0</td>
        <td style="text-align: right">nan</td>
        <td style="text-align: right">0.006</td>
        <td style="text-align: right">65</td>
      </tr>
    </tbody>
  </table>

</div>

<p>A little investigation shows that everywhere <code class="language-plaintext highlighter-rouge">distmod</code> is missing, the redshift values are all zero. The same is true in reverse. The redshift values are tied to a host galaxy. If they are zero and there is no <code class="language-plaintext highlighter-rouge">distmod</code>, I’m almost positive it means that these objects are inside of our own Milky Way galaxy. I’m going to fill the NaN values for <code class="language-plaintext highlighter-rouge">distmod</code> to zero and add a <code class="language-plaintext highlighter-rouge">milky_way</code> boolean, though I’m pretty sure that XGBoost will learn this on it’s own by drawing a decision boundary at zero on this feature in a stump.</p>

<p>I’d also like to take a look at the correlation between the redshift features and <code class="language-plaintext highlighter-rouge">distmod</code>.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/lsst/redshift_corr.png" width="75%" />
  <br />
    <em>Figure 2: Correlation between redshift features and distmod. </em>
</p>

<p>As expected, these features are highly correlated. If I was working with any type of model besides a decision tree, I would use a dimensionality reduction strategy like Principle Component Analysis to reduce them to one or two high variance features. But I think that would be redundant with XGBoost.</p>

<h3 id="light-curve-data">Light Curve Data</h3>

<p>Now on to the more interesting dataset, the light curves! I think the most important thing to look at is how long these are - are they uniform length (number of observations)? Are there uniform steps? Do they represent the same duration?</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/lsst/num_steps.png" width="75%" />
  <br />
    <em>Figure 3: The distribution of number of observations per object. </em>
</p>

<p>The light curves have different numbers of observations, but there seems to be three clusters around 125, 250, and 330.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/lsst/observation.png" width="75%" />
  <br />
    <em>Figure 4: The distribution of observation periods in days. </em>
</p>

<p>There is variation here, but it seems like most of the observations take place over a period of a little over two years or three years.</p>

<p align="center" style="font-size: 12px;">
  <img alt="img-name" src="/images/lsst/step_size.png" width="75%" />
  <br />
    <em>Figure 5: The distribution of average step sizes. </em>
</p>

<p>There also seems to be a significant amount of variation in average step size, and that the observations are taken once or twice a week.</p>

<p>These observations are taken with different passbands, representing different wavelengths of light. This means that there are different light curves for each passband, and when I am feature engineering I plan to split the light curve analysis on this feature.</p>

<p align="center" style="font-size: 12px;">
   <img alt="img-name" src="/images/lsst/passband_dist.png" width="75%" />
   <br />
     <em>Figure 6: The distribution passbands used across all observations. </em>
</p>

<p>They are fairly evenly distributed. Let’s take a look at that these observations look like plotted together.</p>

<p align="center" style="font-size: 12px;">
   <img alt="img-name" src="/images/lsst/random_curve_dots.png" width="100%" />
   <br />
     <em>Figure 7: Random samples of light curves with passbands separated by color. </em>
</p>

<p>We can see that where the passbands overlap on a scale of a few hundred flux or less, there is often a clear separation along the y axis. We can also see that different passband measurements are taken on different days. This leads me to believe that analyzing the light curves separately is the way to go.</p>

<p>Let’s look at what these light curves actually look like. In Figure 8, each column represents a distinct object while the rows iterate through passbands.</p>

<p align="center" style="font-size: 12px;">
   <img alt="img-name" src="/images/lsst/passband_breakdown.png" width="100%" />
   <br />
     <em>Figure 8: Three light curves (columns) separated by passband (rows). Red stars represent detections. </em>
</p>

<p>We can see that each curve has a unique shape and is spread over a different range. But that said, these data points are collected with days, weeks, months, or even years in between them and we aren’t looking at the full picture. This explains in part why my attempt at an sequential analysis was unsuccessful, and why extracted metadata broken down by passband such as min, max, skew, etc. has the potential to be more useful than the sequence of steps.</p>

<p>Let’s take one more look at the light curves, this time with the passbands combined.</p>

<p align="center" style="font-size: 12px;">
   <img alt="img-name" src="/images/lsst/sample_all_types_flux.png" width="100%" />
   <br />
     <em>Figure 9: Two light curves over all passbands from each object type. Red stars represent detections. </em>
</p>

<p>99.9% of the <code class="language-plaintext highlighter-rouge">flux</code> values are under 9,300, but there are outliers up to 2,432,808. Figure 10 shows a graph of the empirical cumulative distribution function for flux values, with the vertical line at the 97.5 percentile mark.</p>

<p align="center" style="font-size: 12px;">
   <img alt="img-name" src="/images/lsst/flux_ecdf.png" width="75%" />
   <br />
     <em>Figure 10: Empirical cumulative distribution function of flux. </em>
</p>

<p>These extreme outliers don’t seem to be noise, but rather predictors of classes 6, 53, and 92.</p>

<h2 id="feature-engineering">Feature Engineering</h2>

<p>My strategy for feature engineering was to extract a handful of features for the metadata, such as <code class="language-plaintext highlighter-rouge">milky_way</code> and <code class="language-plaintext highlighter-rouge">distance</code>, and then extract a large number of descriptive statistics from the light curve data.</p>

<p>For the light curve data, I grouped by <code class="language-plaintext highlighter-rouge">object_id</code> and split the data by passband, then used Pandas aggregate to calculate these statistics.</p>

<p>I added new features incrementally, training an XGBoost model and returning the feature importance. The biggest shakeups were the percentiles and luminosity, which quickly dominated the top thirty list.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">q25</span><span class="p">(</span><span class="n">x</span><span class="p">):</span>
    <span class="k">return</span> <span class="nb">sorted</span><span class="p">(</span><span class="nb">list</span><span class="p">(</span><span class="n">x</span><span class="p">))[</span><span class="nb">int</span><span class="p">(</span><span class="mf">0.25</span><span class="o">*</span><span class="nb">len</span><span class="p">(</span><span class="n">x</span><span class="p">))]</span>

<span class="k">def</span> <span class="nf">q75</span><span class="p">(</span><span class="n">x</span><span class="p">):</span>
    <span class="k">return</span> <span class="nb">sorted</span><span class="p">(</span><span class="nb">list</span><span class="p">(</span><span class="n">x</span><span class="p">))[</span><span class="nb">int</span><span class="p">(</span><span class="mf">0.75</span><span class="o">*</span><span class="nb">len</span><span class="p">(</span><span class="n">x</span><span class="p">))]</span>

<span class="k">def</span> <span class="nf">q95</span><span class="p">(</span><span class="n">x</span><span class="p">):</span>
    <span class="k">return</span> <span class="nb">sorted</span><span class="p">(</span><span class="nb">list</span><span class="p">(</span><span class="n">x</span><span class="p">))[</span><span class="nb">int</span><span class="p">(</span><span class="mf">0.95</span><span class="o">*</span><span class="nb">len</span><span class="p">(</span><span class="n">x</span><span class="p">))]</span>

<span class="n">groupby_dic</span> <span class="o">=</span> <span class="p">{</span>
    <span class="s">'flux'</span> <span class="p">:</span> <span class="p">[</span><span class="s">'min'</span><span class="p">,</span> <span class="s">'max'</span><span class="p">,</span> <span class="s">'mean'</span><span class="p">,</span> <span class="s">'std'</span><span class="p">,</span> <span class="s">'skew'</span><span class="p">,</span> <span class="n">q25</span><span class="p">,</span> <span class="n">q75</span><span class="p">,</span> <span class="n">q95</span><span class="p">],</span>  
    <span class="s">'flux_err'</span> <span class="p">:</span> <span class="p">[</span><span class="s">'min'</span><span class="p">,</span> <span class="s">'max'</span><span class="p">,</span> <span class="s">'mean'</span><span class="p">,</span> <span class="s">'std'</span><span class="p">,</span> <span class="s">'skew'</span><span class="p">],</span>
    <span class="s">'luminosity'</span> <span class="p">:</span> <span class="p">[</span><span class="s">'min'</span><span class="p">,</span> <span class="s">'max'</span><span class="p">,</span> <span class="s">'mean'</span><span class="p">,</span> <span class="s">'std'</span><span class="p">,</span> <span class="s">'skew'</span><span class="p">,</span> <span class="n">q25</span><span class="p">,</span> <span class="n">q75</span><span class="p">,</span> <span class="n">q95</span><span class="p">],</span>
    <span class="s">'detected'</span> <span class="p">:</span> <span class="p">[</span><span class="s">'count'</span><span class="p">,</span> <span class="s">'mean'</span><span class="p">],</span>
    <span class="s">'flux_steps'</span> <span class="p">:</span> <span class="p">[</span><span class="s">'mean'</span><span class="p">,</span> <span class="s">'std'</span><span class="p">]</span>
<span class="p">}</span>

<span class="k">def</span> <span class="nf">process_data</span><span class="p">(</span><span class="n">df</span><span class="p">,</span> <span class="n">df_meta</span><span class="p">,</span> <span class="n">groupby_dic</span> <span class="p">):</span>
    <span class="n">df_meta</span><span class="p">.</span><span class="n">index</span> <span class="o">=</span> <span class="n">df_meta</span><span class="p">.</span><span class="n">object_id</span>
    <span class="n">df_meta</span><span class="p">.</span><span class="n">index</span><span class="p">.</span><span class="n">name</span> <span class="o">=</span> <span class="bp">None</span>

    <span class="c1"># If distmod is null, the object is local.
</span>    <span class="n">df_meta</span><span class="p">[</span><span class="s">'milky_way'</span><span class="p">]</span> <span class="o">=</span> <span class="n">df_meta</span><span class="p">.</span><span class="n">distmod</span><span class="p">.</span><span class="n">isnull</span><span class="p">()</span>

    <span class="c1"># Change missing distmod to zero
</span>    <span class="n">df_meta</span><span class="p">.</span><span class="n">distmod</span><span class="p">.</span><span class="n">fillna</span><span class="p">(</span><span class="mf">0.0</span><span class="p">,</span> <span class="n">inplace</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>

    <span class="c1"># Calculate Luminosity
</span>    <span class="n">df_meta</span><span class="p">[</span><span class="s">'distance'</span><span class="p">]</span> <span class="o">=</span> <span class="n">Distance</span><span class="p">(</span><span class="n">distmod</span><span class="o">=</span><span class="n">df_meta</span><span class="p">.</span><span class="n">distmod</span><span class="p">)</span>
    <span class="n">df</span> <span class="o">=</span> <span class="n">df</span><span class="p">.</span><span class="n">merge</span><span class="p">(</span><span class="n">df_meta</span><span class="p">[[</span><span class="s">'object_id'</span><span class="p">,</span> <span class="s">'distance'</span><span class="p">]],</span> <span class="n">on</span><span class="o">=</span><span class="s">'object_id'</span><span class="p">)</span>
    <span class="n">df</span><span class="p">[</span><span class="s">'luminosity'</span><span class="p">]</span> <span class="o">=</span> <span class="mi">4</span> <span class="o">*</span> <span class="n">np</span><span class="p">.</span><span class="n">pi</span> <span class="o">*</span> <span class="n">df</span><span class="p">.</span><span class="n">flux</span> <span class="o">*</span> <span class="n">df</span><span class="p">.</span><span class="n">distance</span>
    <span class="n">df</span><span class="p">.</span><span class="n">drop</span><span class="p">(</span><span class="s">'distance'</span><span class="p">,</span> <span class="n">axis</span><span class="o">=</span><span class="mi">1</span><span class="p">,</span> <span class="n">inplace</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>

    <span class="c1"># Calculate flux step sizes
</span>    <span class="n">df</span><span class="p">[</span><span class="s">'flux_steps'</span><span class="p">]</span> <span class="o">=</span> <span class="n">df</span><span class="p">.</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">)[</span><span class="s">'flux'</span><span class="p">].</span><span class="n">diff</span><span class="p">().</span><span class="n">fillna</span><span class="p">(</span><span class="mi">0</span><span class="p">)</span>

    <span class="c1"># Aggregate statistics grouped on object_id and passband
</span>    <span class="n">agg</span> <span class="o">=</span> <span class="n">pd</span><span class="p">.</span><span class="n">DataFrame</span><span class="p">(</span><span class="n">index</span><span class="o">=</span><span class="n">df_meta</span><span class="p">.</span><span class="n">object_id</span><span class="p">)</span>
    <span class="n">agg</span><span class="p">[</span><span class="s">'object_id'</span><span class="p">]</span> <span class="o">=</span> <span class="n">df_meta</span><span class="p">.</span><span class="n">object_id</span>
    <span class="k">for</span> <span class="n">pb</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">6</span><span class="p">):</span>
        <span class="n">temp</span> <span class="o">=</span> <span class="n">df</span><span class="p">[</span><span class="n">df</span><span class="p">.</span><span class="n">passband</span><span class="o">==</span><span class="n">pb</span><span class="p">].</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">).</span><span class="n">agg</span><span class="p">(</span><span class="n">groupby_dic</span><span class="p">)</span>
        <span class="n">temp</span><span class="p">.</span><span class="n">columns</span> <span class="o">=</span> <span class="p">[</span><span class="s">'pb'</span> <span class="o">+</span> <span class="nb">str</span><span class="p">(</span><span class="n">pb</span><span class="p">)</span> <span class="o">+</span> <span class="s">'_'</span> <span class="o">+</span> <span class="s">'_'</span><span class="p">.</span><span class="n">join</span><span class="p">(</span><span class="n">c</span><span class="p">)</span> <span class="k">for</span> <span class="n">c</span> <span class="ow">in</span> <span class="n">temp</span><span class="p">.</span><span class="n">columns</span><span class="p">]</span>
        <span class="n">agg</span> <span class="o">=</span> <span class="n">agg</span><span class="p">.</span><span class="n">join</span><span class="p">(</span><span class="n">temp</span><span class="p">)</span>
    <span class="k">del</span><span class="p">(</span><span class="n">temp</span><span class="p">)</span>

    <span class="c1"># Light curve features not in aggregate statistics
</span>    <span class="n">df_meta</span><span class="p">[</span><span class="s">'duration'</span><span class="p">]</span> <span class="o">=</span> <span class="n">df</span><span class="p">[</span><span class="n">df</span><span class="p">.</span><span class="n">detected</span> <span class="o">==</span> <span class="mi">1</span><span class="p">].</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">).</span><span class="n">mjd</span><span class="p">.</span><span class="nb">max</span><span class="p">()</span> <span class="o">-</span> <span class="n">df</span><span class="p">[</span><span class="n">df</span><span class="p">.</span><span class="n">detected</span> <span class="o">==</span> <span class="mi">1</span><span class="p">].</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">).</span><span class="n">mjd</span><span class="p">.</span><span class="nb">min</span><span class="p">()</span>

    <span class="n">df_meta</span><span class="p">[</span><span class="s">'total_duration'</span><span class="p">]</span> <span class="o">=</span> <span class="n">df</span><span class="p">.</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">).</span><span class="n">mjd</span><span class="p">.</span><span class="nb">max</span><span class="p">()</span> <span class="o">-</span> <span class="n">df</span><span class="p">.</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">).</span><span class="n">mjd</span><span class="p">.</span><span class="nb">min</span><span class="p">()</span>

    <span class="n">df_meta</span><span class="p">[</span><span class="s">'back_duration'</span><span class="p">]</span> <span class="o">=</span> <span class="n">np</span><span class="p">.</span><span class="nb">abs</span><span class="p">(</span><span class="n">df</span><span class="p">.</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">).</span><span class="n">mjd</span><span class="p">.</span><span class="nb">max</span><span class="p">()</span> <span class="o">-</span> <span class="n">df</span><span class="p">[</span><span class="n">df</span><span class="p">.</span><span class="n">detected</span> <span class="o">==</span> <span class="mi">1</span><span class="p">].</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">).</span><span class="n">mjd</span><span class="p">.</span><span class="nb">min</span><span class="p">())</span>

    <span class="n">df_meta</span><span class="p">[</span><span class="s">'front_duration'</span><span class="p">]</span> <span class="o">=</span> <span class="n">np</span><span class="p">.</span><span class="nb">abs</span><span class="p">(</span><span class="n">df</span><span class="p">.</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">).</span><span class="n">mjd</span><span class="p">.</span><span class="nb">min</span><span class="p">()</span> <span class="o">-</span> <span class="n">df</span><span class="p">[</span><span class="n">df</span><span class="p">.</span><span class="n">detected</span> <span class="o">==</span> <span class="mi">1</span><span class="p">].</span><span class="n">groupby</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">).</span><span class="n">mjd</span><span class="p">.</span><span class="nb">min</span><span class="p">())</span>

    <span class="k">return</span> <span class="n">df_meta</span><span class="p">.</span><span class="n">object_id</span><span class="p">,</span> <span class="n">df_meta</span><span class="p">.</span><span class="n">join</span><span class="p">(</span><span class="n">agg</span><span class="p">.</span><span class="n">drop</span><span class="p">(</span><span class="s">'object_id'</span><span class="p">,</span> <span class="n">axis</span><span class="o">=</span><span class="mi">1</span><span class="p">)).</span><span class="n">drop</span><span class="p">([</span><span class="s">'object_id'</span><span class="p">,</span> <span class="s">'target'</span><span class="p">],</span> <span class="n">axis</span><span class="o">=</span><span class="mi">1</span><span class="p">),</span> <span class="n">df_meta</span><span class="p">.</span><span class="n">target</span>

<span class="n">_</span><span class="p">,</span> <span class="n">X</span><span class="p">,</span> <span class="n">y</span> <span class="o">=</span> <span class="n">process_data</span><span class="p">(</span><span class="n">df</span><span class="p">,</span> <span class="n">df_meta</span><span class="p">,</span> <span class="n">groupby_dic</span><span class="p">)</span>

<span class="n">X_train</span><span class="p">,</span> <span class="n">X_test</span><span class="p">,</span> <span class="n">y_train</span><span class="p">,</span> <span class="n">y_test</span> <span class="o">=</span> <span class="n">train_test_split</span><span class="p">(</span><span class="n">X</span><span class="p">,</span> <span class="n">y</span><span class="p">,</span> <span class="n">test_size</span><span class="o">=</span><span class="mf">0.3</span><span class="p">,</span> <span class="n">random_state</span><span class="o">=</span><span class="n">RANDOM</span><span class="p">)</span>
</code></pre></div></div>

<p>Note: Pandas does have a built-in quantile function that would be more Pythonic, but it has exponential complexity versus my O(n log n) implementation. Total training time dropped from almost 20 minutes to 37 seconds when I changed from the Pandas implementation to the sorted list implementation above.</p>

<p align="center" style="font-size: 12px;">
   <img alt="img-name" src="/images/lsst/feature_importance_2.png" width="95%" />
   <br />
     <em>Figure 11: Top thirty most important features in the XGBoost model. </em>
</p>

<h2 id="machine-learning">Machine Learning</h2>

<h3 id="evaluation">Evaluation</h3>

<p>Because this is a classification problem, I chose to evaluate it with a combination of the confusion matrix and the F1 score.</p>

<p>A <a href="https://en.wikipedia.org/wiki/Confusion_matrix" target="_blank">confusion matrix</a> is a table of truth values versus predicted values, where the diagonal represents accurate predictions and other cells represent error.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">plot_confusion_matrix</span><span class="p">(</span><span class="n">true</span><span class="p">,</span> <span class="n">pred</span><span class="p">,</span> <span class="n">classes</span><span class="p">,</span> <span class="n">title</span><span class="o">=</span><span class="s">'Confusion Matrix'</span><span class="p">,</span> <span class="n">figsize</span><span class="o">=</span><span class="p">(</span><span class="mi">10</span><span class="p">,</span><span class="mi">8</span><span class="p">),</span> <span class="n">normalize</span><span class="o">=</span><span class="s">'true'</span><span class="p">):</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">figure</span><span class="p">(</span><span class="n">title</span><span class="p">,</span> <span class="n">figsize</span><span class="o">=</span><span class="n">figsize</span><span class="p">)</span>
    <span class="n">cm</span> <span class="o">=</span> <span class="n">sklearn</span><span class="p">.</span><span class="n">metrics</span><span class="p">.</span><span class="n">confusion_matrix</span><span class="p">(</span><span class="n">true</span><span class="p">,</span> <span class="n">pred</span><span class="p">,</span> <span class="n">normalize</span><span class="o">=</span><span class="n">normalize</span><span class="p">)</span>
    <span class="n">sns</span><span class="p">.</span><span class="n">heatmap</span><span class="p">(</span><span class="n">cm</span><span class="p">,</span> <span class="n">cmap</span><span class="o">=</span><span class="s">'bwr'</span><span class="p">,</span> <span class="n">annot</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">title</span><span class="p">(</span><span class="n">title</span><span class="p">,</span> <span class="n">fontsize</span><span class="o">=</span><span class="mi">28</span><span class="p">)</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">xlabel</span><span class="p">(</span><span class="s">"Predicted"</span><span class="p">,</span> <span class="n">fontsize</span><span class="o">=</span><span class="mi">18</span><span class="p">)</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">xticks</span><span class="p">([</span><span class="n">i</span><span class="o">+</span><span class="mf">0.5</span> <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="nb">len</span><span class="p">(</span><span class="n">classes</span><span class="p">))],</span> <span class="n">classes</span><span class="p">)</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">yticks</span><span class="p">([</span><span class="n">i</span><span class="o">+</span><span class="mf">0.5</span> <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="nb">len</span><span class="p">(</span><span class="n">classes</span><span class="p">))],</span> <span class="n">classes</span><span class="p">)</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">ylabel</span><span class="p">(</span><span class="s">"Truth"</span><span class="p">,</span> <span class="n">fontsize</span><span class="o">=</span><span class="mi">18</span><span class="p">)</span>
    <span class="n">plt</span><span class="p">.</span><span class="n">show</span><span class="p">()</span>
</code></pre></div></div>

<p align="center" style="font-size: 12px;">
   <img alt="img-name" src="/images/lsst/example_cm.png" width="45%" />
   <br />
     <em>Figure 12: An example confusion matrix. </em>
</p>

<p>Accuracy can be deceiving in unbalanced classes. Say you have 1,000 rows and 990 are true, but it’s really important to properly classify those ten that aren’t as false. If accuracy is you metric, you can simply make a model that predicts <code class="language-plaintext highlighter-rouge">y = 1</code> and call it a day with 99% accuracy.</p>

<p>Precision is the ratio of true positive results to the predicted positive results, or the true positive and false positives  (also known as Type I error) combined. This tells us what percentage of the positive predictions were correct.</p>

<p>Recall is the ratio of positive predictions to all positive values, or the combination of true positives and false negatives (also know as Type II error). This shows us what portion of the positive results we captured.</p>

<p>On their own, precision and recall are deeply flawed metrics for evaluating a model. You could achieve perfect precision with a model that simply states <code class="language-plaintext highlighter-rouge">y = 0</code>, and perfect recall with a model that states <code class="language-plaintext highlighter-rouge">y = 1</code>.</p>

<p>This is where the F1 Score comes in. The F1 score is the harmonic mean between precision and recall and offers a balanced model score. Between the F1 score and the confusion matrix, it becomes easy to see how changes to model parameters impact performance.</p>

<h3 id="xgboost">XGBoost</h3>

<p>XGBoost is a gradient boosted tree implementation.</p>

<p>A typical decision tree model like random forest aggregates multiple individual decision trees and has them vote on a solution. The ensembled models are fully grown decision trees trained in parallel and the results are averaged. There is low bias (error introduced by the model), but high variance (error from fluctuations in the training set). This means that the models are prone to overfitting, or memorizing the training data and not generalizing well to unseen data.</p>

<p>Gradient boosted tree models improve on the random forest concept by training the individual trees sequentially with gradient descent. It’s still an ensemble of decision trees, but with a much different strategy. The trees in gradient boosting are also not fully grown, but rather an ensemble of weak learners including stumps with a depth of two. These weak learners have high bias and low variance, but gradient boosting reduces the error due to bias.</p>

<p>The result is a powerful model that can fit to highly nonlinear data without overfitting, while having more describeability than black box algorithms like neural networks.</p>

<h3 id="training">Training</h3>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">model</span> <span class="o">=</span> <span class="n">XGBClassifier</span><span class="p">()</span>  
<span class="n">model</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">X_train</span><span class="p">,</span> <span class="n">y_train</span><span class="p">)</span>
<span class="n">y_pred</span> <span class="o">=</span> <span class="n">model</span><span class="p">.</span><span class="n">predict</span><span class="p">(</span><span class="n">X_test</span><span class="p">)</span>
</code></pre></div></div>

<p>I began the model training process by simply benchmarking the model on my initial engineered features (those described in the <code class="language-plaintext highlighter-rouge">groupby_dic</code> in the code block above) and the default parameters. It achieved a very strong performance of:</p>

<p>Precision: 0.7883
Recall: 0.8081
F1: 0.7867</p>

<p>Unlike the previous project in my independent study, which was an image description problem with clear data and the biggest impact to performance was optimization of the architecture of a neural network, this problem is messier and the biggest opportunity to optimize performance is in feature engineering.</p>

<p>After several rounds of feature engineering, I was able to achieve a 3.5% boost in precision, a little over half a percent boost in recall, and a 1.2% boost in the F1 score.</p>

<p>Precision: 0.8155
Recall: 0.8153
F1: 0.7964</p>

<p>Satisfied that I had found a good selection of features, I moved on to hyperparameter tuning. I did a random sweep of the features I believed would have the biggest impact on the model: the number of estimators, the max depth of the trees, and the gamma (a regularization parameter).</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">params</span> <span class="o">=</span> <span class="p">{</span>
        <span class="s">'gamma'</span><span class="p">:</span> <span class="p">[</span><span class="mf">0.5</span><span class="p">,</span> <span class="mi">1</span><span class="p">,</span> <span class="mf">1.5</span><span class="p">,</span> <span class="mi">2</span><span class="p">,</span> <span class="mi">5</span><span class="p">],</span>
        <span class="s">'n_estimators'</span><span class="p">:</span> <span class="p">[</span><span class="mi">100</span><span class="p">,</span> <span class="mi">250</span><span class="p">,</span> <span class="mi">500</span><span class="p">],</span>
        <span class="s">'max_depth'</span><span class="p">:</span> <span class="p">[</span><span class="mi">3</span><span class="p">,</span> <span class="mi">4</span><span class="p">,</span> <span class="mi">5</span><span class="p">]</span>
        <span class="p">}</span>
<span class="n">model</span> <span class="o">=</span> <span class="n">XGBClassifier</span><span class="p">()</span>
<span class="n">skf</span> <span class="o">=</span> <span class="n">sklearn</span><span class="p">.</span><span class="n">model_selection</span><span class="p">.</span><span class="n">StratifiedKFold</span><span class="p">(</span><span class="n">n_splits</span><span class="o">=</span><span class="mi">4</span><span class="p">,</span> <span class="n">shuffle</span> <span class="o">=</span> <span class="bp">True</span><span class="p">,</span> <span class="n">random_state</span> <span class="o">=</span> <span class="n">RANDOM</span><span class="p">)</span>
<span class="n">random_search</span> <span class="o">=</span> <span class="n">sklearn</span><span class="p">.</span><span class="n">model_selection</span><span class="p">.</span><span class="n">RandomizedSearchCV</span><span class="p">(</span><span class="n">model</span><span class="p">,</span> <span class="n">param_distributions</span><span class="o">=</span><span class="n">params</span><span class="p">,</span> <span class="n">n_iter</span><span class="o">=</span><span class="mi">5</span><span class="p">,</span> <span class="n">cv</span><span class="o">=</span><span class="n">skf</span><span class="p">.</span><span class="n">split</span><span class="p">(</span><span class="n">X_train</span><span class="p">,</span> <span class="n">y_train</span><span class="p">),</span> <span class="n">n_jobs</span><span class="o">=</span><span class="mi">4</span><span class="p">,</span> <span class="n">verbose</span><span class="o">=</span><span class="mi">3</span><span class="p">,</span> <span class="n">random_state</span><span class="o">=</span><span class="n">RANDOM</span> <span class="p">)</span>
<span class="n">random_search</span><span class="p">.</span><span class="n">fit</span><span class="p">(</span><span class="n">X</span><span class="p">,</span> <span class="n">y</span><span class="p">)</span>
</code></pre></div></div>

<p>The optimal selections were 1.5 gamma, 500 estimators, and a max depth of 5. Since the estimators and depth were at the edge of the parameter grid, I repeated the experiment twice taking one extra step for each parameter and saw performance decrease. Therefore, the final parameter grid was:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">params</span> <span class="o">=</span> <span class="p">{</span><span class="s">'gamma'</span><span class="p">:</span><span class="mf">1.5</span><span class="p">,</span>
          <span class="s">'max_depth'</span><span class="p">:</span><span class="mi">5</span><span class="p">,</span>
          <span class="s">'n_estimators'</span><span class="p">:</span><span class="mi">500</span><span class="p">}</span>
</code></pre></div></div>

<p>The result? A 4.5% boost in precision, a 1.7% boost in recall, and a 2.2% boost in F1 score.</p>

<p>Precision: 0.8239
Recall: 0.8221
F1: 0.8038</p>

<p>Let’s take a look at the confusion matrix to see how this breaks down in terms of accuracy across target classes.</p>

<p align="center" style="font-size: 12px;">
   <img alt="img-name" src="/images/lsst/final_cm.png" width="75%" />
   <br />
     <em>Figure 13: Confusion matrix illustrating the performance of the final model. </em>
</p>

<p>We can see a mix of performance across classes. Some perform very strong, while a few are not captured well. This actually presents an interesting problem, and many participants in the Kaggle challenge struggled with these as well.</p>

<p>In machine learning problems, not every class or cluster of data is guaranteed to be well suited for the same model. The solution to this is ensemble models, training multiple different types of models on either the full dataset or clusters of the data and having another model trained on the output. To see an example of ensembling and stacking, you can check out my entry in the <a href="https://www.kaggle.com/jayspeidell/predictions-as-features" target="_blank">Mercari Price Prediction Challenge</a> where I used a boosted tree model on the output of another boosted tree and a linear regression model to get about 7% better performance than either model individually.</p>

<p>There is a fundamental tradeoff in machine learning between the complexity of a model, in terms of not only Big O and computational overhead but also the engineer’s time and expertise, and the performance of the model.</p>

<p>For this project, I’m happy with this single model performance and it was a great exercise in feature engineering.</p>

<h2 id="closing-thoughts">Closing Thoughts</h2>

<p>This was a fun project and I significantly expanded my skill level with Pandas and feature engineering, and I also learned a new gradient boosted tree library.</p>

<p>And even though it didn’t make the cut, I gained a deeper knowledge of recurrent neural networks and time series data pipelines in PyTorch. I’m looking forward to applying that knowledge to new problems with data better fit to that strategy.</p>]]></content><author><name>Jay Speidell</name><email>jayspeidell@gmail.com</email></author><category term="data science" /><summary type="html"><![CDATA[This is a sequence analysis project that I completed for my independent study at Old Dominion University. I used the open source dataset from Kaggle's PLAsTiCC Astronomical Classification Challenge. In the project I analyzed light curves, engineered over a hundred metadata features, and built a LightGBM model to predict the object classes.]]></summary></entry><entry><title type="html">Toxic Comment Classification - Natural Language Processing</title><link href="https://jayspeidell.github.io/posts/toxic-comment-analysis/" rel="alternate" type="text/html" title="Toxic Comment Classification - Natural Language Processing" /><published>2020-07-19T00:00:00-07:00</published><updated>2020-07-19T00:00:00-07:00</updated><id>https://jayspeidell.github.io/posts/toxic-comments</id><content type="html" xml:base="https://jayspeidell.github.io/posts/toxic-comment-analysis/"><![CDATA[<hr />
<p>title: “Toxic Comment Classification - Natural Language Processing”
excerpt: “I performed a detailed analysis of Wikipedia comments and built a model that classifies them as toxic or nontoxic. The final model is a support vector machine that uses a Naive Bayes feature weight transformer to improve performance. The data was obtained from Kaggle. “
collection: portfolio
—</p>

<p><a href="https://github.com/jayspeidell/ToxicCommentClassification-">The Jypyter notebooks and a report in PDF format can be found on my GitHub page here.</a></p>

<p><img src="/images/toxic/wordcloud.png" style="width:100%" /></p>
<h1 id="i-definition">I. Definition</h1>
<h2 id="project-overview">Project Overview</h2>

<p>Platforms that aggregate user content are the foundation of knowledge sharing on the Internet. Blogs, forums, discussion boards, and, of course, Wikipedia. But the catch is that not all people on the Internet are interested in participating nicely, and some see it as an avenue to vent their rage, insecurity, and prejudices.</p>

<p>Wikipedia runs on user generated content, and is dependent on user discussion to curate and approve content. The problem with this is that people will frequently write things they shouldn’t, and to maintain a positive community this toxic content and the users posting it need to be removed quickly. But they don’t have the resources to hire full-time moderators to review every comment.</p>

<p>This problem led the Conversation AI team<sup><a href="#resources">1</a></sup>, owned by Alphabet, to develop a large open dataset of labeled Wikipedia Talk Page comments, which will be the dataset used for the project. The dataset is available through Kaggle<sup><a href="#resources">2</a></sup>.</p>

<p>The dataset has six labels that represent subcategories of toxicity, but the project is going to focus on a seventh label that represents the general toxicity of the comments.</p>

<p>The project will be done with Python and Jupyter notebooks, which will be attached.</p>

<p>Disclaimer: The dataset has extremely offensive language that will show up during exploratory data analysis.</p>

<h2 id="problem-statement">Problem Statement</h2>
<p>The goal is to create a classifier model that can predict if input text is inappropriate (toxic).
    1. Explore the dataset to get a better picture of how the labels are distributed, how they correlate with each other, and what defines toxic or clean comments.
    2. Create a baseline score with a simple logistic regression classifier.
    3. Explore the effectiveness of multiple machine learning approaches and select the best for this problem.
    4. Select the best model and tune the parameters to maximize performance.
    5. Build a the final model with the best performing algorithm and parameters and test it on a holdout subset of the data.</p>

<h2 id="metrics">Metrics</h2>
<p>Unfortunately for the problem, but fortunately for the Wikipedia community, toxic comments are rare. Just over 10% of this dataset is labeled as toxic, but some of the subcategories are extremely rare making up less than 1% of the data.</p>

<p>Because of this imbalance, accuracy is a practically useless metric for evaluating classifiers for this problem.</p>

<p>The Kaggle challenge based on this dataset uses ROC/AUC, or the area under a receiver operating characteristic curve, to evaluate submissions. This is a very generous metric for the challenge, as axes for the curve represent recall (a.k.a. sensitivity), the ratio of positive predictions to all samples with that label, and specificity, the ratio of negative predictions to all negative samples. This metric would work well if the positive and negative labels were relatively even, but in our case, where one label represents less than a third of a percent of the data, it’s too easy to get a high score even with hardly any true-positive predictions.</p>

<p>Instead, I propose using an F1 Score, which severely penalizes models that just predict everything as either positive or negative with an imbalanced dataset.</p>

<p>Recall, as mentioned earlier, is the ratio of true positive predictions to positive samples. Precision, on the other hand, is the ratio of true positive predictions to the sum of all positive predictions, true and false.</p>

<p>Each gives valuable insight into a model’s performance, but they fail to show the whole picture and have weaknesses where bad models get high scores. Predicting all positive values will bring recall up to 100%, while missing true positives will be penalized. Precision will harshly penalize false positives, but a model that predicts mostly negative can achieve a high precision score whether or not the predictions are accurate.</p>

<p>The F1 score is a harmonic average between precision and recall. This combines the strengths of precision and recall while balancing out their weaknesses, creating a score that can fairly evaluate models regardless of dataset imbalance.</p>

<p>My justification for focusing on any_label as the target is that distinctions between the specific labels are relatively ambiguous, and that there is greater value focusing on general toxicity of a comment to more reliably flag it for review. This will reduce the workload of moderators who will ultimately be making the final call, and the specific category more relates to the consequences for the commenter rather than whether or not the comment should be deleted.</p>

<h1 id="ii-analysis">II. Analysis</h1>
<p>Data Exploration
This dataset contains 159,571 comments from Wikipedia. The data consists of one input feature, the string data for the comments, and six labels for different categories of toxic comments: toxic, severe_toxic, obscene, threat, insult, and identity_hate.
The figure on the following page contains a breakdown of how the labels are distributed throughout the dataset, including overlapping data.
As you can see in the breakdown, while most comments with other labels are also toxic, not all of them are. Only “severe_toxic” is clearly a subcategory of “toxic.” And it’s not close enough to be a labeling error. This suggests that “toxic” is not a catch-all label, but rather a subcategory in itself with a large amount of overlap. Because of this, I’m going to create a seventh label called “any_label” to represent overall toxicity of a comment. From here on in, I’m going to refer to any labeled comments as toxic, and the specific “toxic” label (along with other labels) in quotation marks.</p>

<p><img src="/images/toxic/label counts.png" style="width:100%" />
<br /><em>Fig 1: Label Counts</em></p>

<p>Only 39% of the toxic comments have only one label, and the majority have some sort of overlap. I believe that because of this, it will be much more difficult to train a classifier on specific labels than whether or not they are toxic.
This ambiguity and the lack of explanation around it is what led me to select an aggregate label of general toxicity, what I’ve called “any_label,” as the target.
16225 out of 159571 comments, or 10.17%, are classified as some category of toxic.</p>

<p>1595 severe_toxic comments. (1.00% of all data.)</p>
<ul>
  <li>1595 or 100.00% were also toxic.</li>
  <li>1517 or 95.11% were also obscene.</li>
  <li>112 or 7.02% were also threat.</li>
  <li>1371 or 85.96% were also insult.</li>
  <li>313 or 19.62% were also identity_hate.</li>
</ul>

<p>1405 identity_hate comments. (0.88% of all data.)</p>
<ul>
  <li>1302 or 92.67% were also toxic.</li>
  <li>313 or 22.28% were also severe_toxic.</li>
  <li>1032 or 73.45% were also obscene.</li>
  <li>98 or 6.98% were also threat.</li>
  <li>1160 or 82.56% were also insult.</li>
</ul>

<p>15294 toxic comments. (9.58% of all data.)</p>
<ul>
  <li>1595 or 10.43% were also severe_toxic.</li>
  <li>7926 or 51.82% were also obscene.</li>
  <li>449 or 2.94% were also threat.</li>
  <li>7344 or 48.02% were also insult.</li>
  <li>1302 or 8.51% were also identity_hate.</li>
</ul>

<p>7877 insult comments. (4.94% of all data.)</p>
<ul>
  <li>7344 or 93.23% were also toxic.</li>
  <li>1371 or 17.41% were also severe_toxic.</li>
  <li>6155 or 78.14% were also obscene.</li>
  <li>307 or 3.90% were also threat.</li>
  <li>1160 or 14.73% were also identity_hate.</li>
</ul>

<p>478 threat comments. (0.30% of all data.)</p>
<ul>
  <li>449 or 93.93% were also toxic.</li>
  <li>112 or 23.43% were also severe_toxic.</li>
  <li>301 or 62.97% were also obscene.</li>
  <li>307 or 64.23% were also insult.</li>
  <li>98 or 20.50% were also identity_hate.</li>
</ul>

<p>8449 obscene comments. (5.29% of all data.)</p>
<ul>
  <li>7926 or 93.81% were also toxic.</li>
  <li>1517 or 17.95% were also severe_toxic.</li>
  <li>301 or 3.56% were also threat.</li>
  <li>6155 or 72.85% were also insult.</li>
  <li>1032 or 12.21% were also identity_hate.</li>
</ul>

<p>The correlation matrix below provides more insight into these overlapping categories. Threats are not likely to be severely toxic, nor are they likely to be racist or homophobic. But insults are often obscene, and identity hate really doesn’t have much overlap at all.</p>

<p>I believe the categories with significant overlap will be more difficult to predict, as they’ll have similar contributing features, but “identity_hate” will have more unique attributes and be easier to predict.</p>

<p><img src="/images/toxic/type heatmap.png" style="width:100%" />
<br /><em>Fig 2: Correlation Matrix Heatmap of Labels</em></p>

<p>So what do these comments look like? Let’s look at a few.</p>

<p>Clean comments:</p>
<ul>
  <li>“By baysian logic the picture is quite relavent. Only someone so opposed to the Vietnam war, as to visit NVN, would support something as tawdry as WSI. The photo is contemporary to the time period of the WSI, and is a very defining picture of one of the key participants during the time period that WSI took place.”</li>
  <li>“Oppose. Other towers have articles, so this one should. 89.242.19.188”</li>
  <li>“This sounds like your opinion.  I’m giving you National Geographic, and GW supporters give me the IPCC, a group of politicians who pick and choose articles that support the idea of anthropogenic global warming and discredit any scientist who dissents.  The reason I toss the term ‘nazi’ around is that it seems this article is loosely guarded by (what I call) a ““gestapo”” that sits around with an arsenal of ““talk-back”” to shoot down anyone who dissents from the idea of man-made GW.  I was talking about the Sun and how other planets are warming.  In my book, this falls under the area of astronomy, which last I checked is a science.  You seem to think science is only opinions that agree that man is causing global warming, and I’m sorry, I don’t agree with that.12.26.68.146”</li>
</ul>

<p>So clean comments can be argumentative and can include name calling, but are generally positive discussions.</p>

<p>The IP addresses in comments are concerning, as that’s a data leak and could cause issues since we want the classifier to predict toxicity based on the content of the comments. Because of this, I’ve used a regular expression to strip all of the IP addresses from the dataset.</p>

<p>I’ve found one other data leak as well: usernames. Removing them without a database of users is an incredibly difficult task. But while removing them completely isn’t an option, the term frequency – inverse document frequency vectorizing strategy should minimize or even eliminate their influence on the model.</p>

<p>Toxic Comments:</p>
<ul>
  <li>“your a cocksucker u can’t do anything to me”</li>
  <li>“What 3 minutes every now and then - I’m not compiling lists and spending fucking hours doing fuck-all because no one loves me - how many edits have you done? Let’s remember - you’re so stupid and indeed pathetic you don’t even use your own name”</li>
  <li>“again again again</li>
  <li>this is not going to stop……hmmmm a personal attack let me think……you are a big poo poo face and smell like a frog”</li>
</ul>

<p>Various types of toxic comments seem to almost always be argumentative, though they don’t necessarily involve profanity. Traditional filters involve a database of profanity to screen comments, but this breaks down when legitimate comments discuss profanity and toxic comments have clean language.</p>

<p>So what does a clean Wikipedia comment look like? I used a tokenizer with the standard stopwords to get the overall count of individual words and plotted the top 45.</p>

<p><img src="/images/toxic/word counts.png" style="width:100%" />
<br /><em>Fig 3: Non-Toxic Comment Word Frequency</em></p>

<p>Article, page, please, think, edit, etc. The highest frequency words are about what you would expect from people discussing Wikipedia page edits and policy.</p>

<p>Now let’s look at what a bad comment looks like. Can you find the top two words from the clean comments? “Wikipedia” surprisingly comes in second, and “article” falls back quite a few spaces. The difference in the highest frequency vocabulary is stark.</p>

<p><img src="/images/toxic/toxic counts.png" style="width:100%" />
<br /><em>Fig 4: Toxic Comment Word Frequency</em></p>

<p>In addition to the words themselves, I’ve extracted some other attributes of the comments that show contrast between toxic and clean comments.</p>

<ul>
  <li>Capitalization<br />
 Toxic comments are more likely to be either in all caps or have no capitalization at all. In an average clean comment, 5% of the characters are capital letters. In toxic comments, that number jumps to 14%. I think this feature will be extremely useful, especially with tree-based models due to it’s nonlinear nature. While the mean percentage of capital letters in toxic comments is almost triple that of clean comments, the medians are the same at 4%. This suggests that while clean comments are consistently capitalized, toxic comments have quite a few outliers. This is confirmed when browsing through the comments, as toxic comments are often all caps or not capitalized at all.</li>
  <li>Comment Length<br />
 On average, clean comments are about a third longer than toxic comments. The average character count for clean comments is 404, while toxic comments average 303 characters. Looking at random samples, many clean comments have very long, well though-out answers. The median comment lengths are 128 characters for toxic comments and 216 characters for clean comments, suggesting that these longer comments make up a significant portion of the dataset for both types of comments.</li>
  <li>Word Length<br />
 This one is a little closer, but there is a difference. Toxic comments average 4.1 characters per word, where clean comments average 4.4. But on a comment-by-comment basis this could be meaningful, as a visual scan shows that many of the toxic comments are more likely to use informal abbreviations like “u.”</li>
  <li>Question Marks<br />
 My thought here is that more legitimate posts might have more question marks. But that assumption was wrong, as toxic comments have 50% more question marks per comment than clean comments. 0.6 versus 0.4.</li>
  <li>Exclamation Marks<br />
 I made the opposite assumption about exclamation marks, and that paid off! Toxic comments have an average of 3.5 exclamation marks, while clean comments only have 0.3. This could be a very useful feature.</li>
</ul>

<h2 id="algorithms-and-techniques">Algorithms and Techniques</h2>

<p>As a natural language processing problem, is a classification task that involves high dimensionality data. I will vectorize the data and test multiple classification algorithms.</p>

<p>I will vectorize the text data using the term frequency – inverse document frequency (tf-idf) statistic. This technique takes into account not only the frequency of words or character n-grams in the text, it also takes into account the relevancy of those tokens across the dataset as a whole. The inverse document frequency reduces the weight of common tokens while boosting the weight of more unique tokens. I will establish a benchmark for performance with the top 10,000 words, and the number of tokens and the mix of words and character n-grams will be a parameter to tune for higher performance later on.</p>

<p>I will also create a number of engineered features containing various attributes of the comment text, such as average word length, capitalization, and number of exclamation points. I will run the benchmark test without these features and experiment with them to optimize the solution.</p>

<p>With the benchmark vectorization and features, I will experiment with multiple algorithms with default parameters to determine the most effective approach to the problem. The models I will use are:</p>
<ul>
  <li>Logistic Regresssion (Benchmark)</li>
  <li>Multinomial Naive Bayes</li>
  <li>Support Vector Machine</li>
  <li>Support Vector Machine with Naive Bayes Features</li>
  <li>Light GBM</li>
</ul>

<p>Recurrent neural networks work well on this problem and top Kaggle leaderboards, but I think deep learning approaches might be too resource intensive for an algorithm that has to run instantly every single time a comment is posted on one of the most popular websites on the Internet. A major requirement if this were a real-life business problem is efficiency. Additionally, adapting the model to secondary features would require stacking, which is a messy solution that increases the complexity of both training and predicting. I’ve used model stacking in Kaggle competitions before, and it comes at the expense of efficiency.</p>

<p>One more consideration is transparency, and this is the biggest aspect of the decision not to use neural networks for this application. I want to have the ability to easily audit the model to ensure that it isn’t picking up bias around race, gender, sexual orientation, culture, or unforeseen categories from the curators of the data. SVM, Naive Bayes, and LightGBM will make it much easier for a third party to analyze the impact of specific features on the model and make appropriate adjustments to combat bias.</p>

<p>I predict that there will be a toss-up between Logistic Regression and Support Vector Machines. Naive Bayes may have strong performance due to the dramatic difference between the the frequency distributions of the vocabulary between comments.</p>

<p>Support vector machine models are unique in that they find the boundaries between classes by looking at the distances between the separating line and the nearest point for each class, and are not effected by outliers. In this project I will be using the linear kernel. The kernel trick with support vector machines involves projecting data with complex or nonlinear boundaries into a higher dimension where they are linearly separable and drawing a hyperplane between them using a linear model algorithm. Imagine a 2D problem where you have a circular boundary between two classes and need to draw your decision boundary with linear regression. With the kernel trick you’d be projecting that flat dataset into the dimensions and ideally the circle would look more like a hill, allowing you to cut through it with a 2D plane and establish a linear boundary. The linear kernel is the most efficient of the kernels and is very resistant to overfitting, which I think may be an issue with the dataset.</p>

<p>LightGBM is a tree-based ensemble model that is trained with gradient boosting. The unique attribute versus other boosted tree algorithms is that it grows leaf-wise rather than level-wise, meaning that it prioritizes width over depth. Boosted tree can be confused with forest models, but there is an important distinction. Where forest models like Scikit-Learn’s RandomForest use an ensemble of fully developed decision trees, boosted tree algorithms use an ensemble of weak learners that may be trained faster and can possibly generalize better on a dataset like this one where there are a very large number of features but only a select few might have an influence on any given comment.</p>

<p>LightGBM is not a high performer on Natural Language Processing tasks, but I think it’s worth trying a tree-based model here due to the very large disparity between toxic and clean comments with the engineered features and top 30 words. There may be some great, reliable splits here. The reason it doesn’t perform well on NLP tasks is that it requires dense input data, and the nature of vectorizing text creates absolutely massive matrices filled mostly with zeros. It also has a relatively small number of features that it can focus on, while the vectorized text may contain over 20,000 features.</p>

<p>Support Vector Machine with Naive Bayes Features or Multinomial Naive Bayes may perform even better. The paper <em>Baselines and Bigrams: Simple, Good Sentiment and Topic Classification</em><sup><a href="#resources">3</a></sup> experiments with this algorithm on a variety of types of datasets and found that Support Vector Machines performed exceptionally well at sentiment analysis on datasets with lengthy texts, such as full-length movie reviews. The same paper suggest that Multinomial Naive Bayes works better on snippets of text. Assuming an average sentence length of 75 to 100 characters, the Wikipedia dataset used in this project averages 2-4 sentences, which is more than a snippet but not exactly lengthy. Naive Bayes with SVM features was found to interpolate between Naive Bayes and Support Vector Machines, combining strengths of each.</p>

<p>After establishing a baseline score for each model, I’ll choose the best one or two, depending on how close they are, and tune the vectorization and model parameters to optimize performance.</p>

<h2 id="baseline">Baseline</h2>
<p>The baseline model is a Logistic Regression model fit to tf-idf vectorized comment text with using only words for tokens, limited to 10,000 features. The target value is any_label, but I also want to track the model’s performance on specific categories. But I do think that it’s important to note that my personal difficulty in perceiving the difference in specific categories when looking through comments is reflected in the model’s ability to specifically predict severe_toxic, threat, and identity_hate labels.</p>

<p>The cross-validated F1 scores for each label break down as follows:</p>
<ul>
  <li>toxic score: 0.7192</li>
  <li>severe_toxic score: 0.3224</li>
  <li>obscene score: 0.7452</li>
  <li>threat score: 0.2069</li>
  <li>insult score: 0.6277</li>
  <li>identity_hate score: 0.2772</li>
  <li>any_label score: 0.7299</li>
</ul>

<p>I also tested a baseline with the engineered features included.</p>
<ul>
  <li>toxic score: 0.7235</li>
  <li>severe_toxic score: 0.3475</li>
  <li>obscene score: 0.7440</li>
  <li>threat score: 0.2029</li>
  <li>insult score: 0.6274</li>
  <li>identity_hate score: 0.2768</li>
  <li>any_label score: 0.7328</li>
</ul>

<p>The scores are nearly identical, but this may not necessarily be the case for all models.</p>
<h1 id="iii-methodology">III. Methodology</h1>
<h2 id="reproducibility">Reproducibility</h2>
<p>I am setting a few parameters at the top of my Jupyter notebook to ensure reproducibility of results, and these will be used in every appropriate instance. This will ensure that the output is exactly the same every time the notebook is run.</p>
<ul>
  <li>seed (for random states) = 42</li>
  <li>k (for n_folds) = 5</li>
</ul>

<p>Experiments that take a significant amount of time, such as
Data Preprocessing</p>

<h2 id="cleaning">Cleaning</h2>
<p>The dataset is relatively clean. There is a minor data leak, IP addresses appended to some comments. For various reasons, mainly that this data may slightly compromise the model’s ability to generalize to new data, I’ve used a regular expression to strip all IP addresses from comments.</p>

<h2 id="feature-engineering">Feature Engineering</h2>
<p>During the exploratory data analysis, I found that many attributes of comments outside of the words themselves may be useful in predicting whether they are toxic. The features I added to the dataset are:</p>
<ul>
  <li>Comment length in characters</li>
  <li>Percent of letters in a comment that are capitalized</li>
  <li>Average length of words in a comment</li>
  <li>Number of exclamation marks in a comment</li>
  <li>Number of question marks in a comment</li>
</ul>

<h2 id="vectorization">Vectorization</h2>
<p>As discussed previously, I am using a term frequency – inverse document frequency (tf-idf) statistic to vectorize text. The number of features and presence of character n-grams is a parameter to tune for model optimization.</p>

<h2 id="feature-scaling">Feature Scaling</h2>
<p>The engineered features are normalized from 0.0 to 1.0. The tf-idf features are not scaled.</p>

<h2 id="implementation">Implementation</h2>
<p>Finding the Best Algorithm
To compare the relative performances of each algorithm, I’m going to test them on the same preprocessed data as the benchmark, a tf-idf vectorized data with 10,000 features. The target is any_label, and the scores are F1 scores with five-fold cross validation.</p>
<ul>
  <li>Logistic Regression:  0.7299
    <ul>
      <li>With engineered features: 0.7328</li>
      <li>Engineered feature boost: 0.39%</li>
    </ul>
  </li>
  <li>Multinomial Naive Bayes (NB):  0.6670 (0 predictions for threat category)
    <ul>
      <li>With engineered features: 0.6734 (0 predictions for threat category)</li>
      <li>Engineered feature boost: 0.96%</li>
    </ul>
  </li>
  <li>Support Vector Machine (SVM): 0.7703
    <ul>
      <li>With engineered features: 0.7739</li>
      <li>Engineered feature boost: 0.47% boost</li>
    </ul>
  </li>
  <li>Support Vector Machine with Naive Bayes Features (NB-SVM): 0.7804
    <ul>
      <li>With engineered features: 0.7842</li>
      <li>Engineered feature boost: 0.49%</li>
    </ul>
  </li>
  <li>LightGBM*: 0.7470
    <ul>
      <li>With engineered features: 0.7573</li>
      <li>Engineered feature boost: 1.38%</li>
    </ul>
  </li>
</ul>

<p>* The other algorithms used default parameters, but LightGBM parameters were modified to better suit an NLP problem as the default parameters aren’t really suited to the problem like they are with other algorithms.</p>

<p>LightGBM Baseline Parameter Modifications:</p>
<ul>
  <li>‘num_leaves’: 64,</li>
  <li>‘n_estimators’: 500,</li>
  <li>‘max_depth’: 16</li>
</ul>

<p>Not surprisingly, the engineered features gave the tree based model a larger performance boost than other models. The performance gain for other algorithms is modest, but it does come at an extremely minimal cost in terms of processing resources and training time so I would consider them worthwhile.</p>

<p>In terms of overall performance, NB-SVM is the strongest performer and SVM comes in at a close second. The naive bayes features gave SVM a 1.31% performance boost at a cost of about five times the training time. Around thirty-five seconds versus a little over three minutes, but the difference is minimal at prediction time and the gain is significant.</p>

<p>LightGBM also showed strong results with some tuning, but there is an issue with the model that prevents it from being a practical solution unless it’s performance is significantly higher than other models. Like all tree-based models, dense data is a firm requirement. Refining the text vectorization strategy is an important aspect of optimizing a natural language processing solution. Linear regression and support vector machines can run on sparse matrices which reduces their memory footprint, but LightGBM will see memory grow too fast converting sparse matrices into dense ones.</p>

<h2 id="refinement-of-the-nb-svm-model">Refinement of the NB-SVM Model</h2>
<h3 id="step-1-optimize-tf-idf-vectorizer">Step 1: Optimize tf-idf vectorizer</h3>
<p>Experiment with word and character level ngrams and maximum feature counts. All other parameters are fixed, and refinement steps will all use five-fold cross validation.</p>

<table>
  <tbody>
    <tr>
      <td><strong>Word Ngram</strong></td>
      <td><strong>Word Max Features</strong></td>
      <td><strong>Char Ngram</strong></td>
      <td><strong>Char Max Features</strong></td>
      <td><strong>Score</strong></td>
    </tr>
    <tr>
      <td>1</td>
      <td>10,000</td>
      <td>0</td>
      <td>0</td>
      <td>0.7842</td>
    </tr>
    <tr>
      <td>1</td>
      <td>30,000</td>
      <td>0</td>
      <td>0</td>
      <td>0.7926</td>
    </tr>
    <tr>
      <td>1-2</td>
      <td>30,000</td>
      <td>0</td>
      <td>0</td>
      <td>0.7877</td>
    </tr>
    <tr>
      <td>2-6</td>
      <td>30,000</td>
      <td>0</td>
      <td>0</td>
      <td>0.4042</td>
    </tr>
    <tr>
      <td>0</td>
      <td>0</td>
      <td>3-7</td>
      <td>20,000</td>
      <td>0.7742</td>
    </tr>
    <tr>
      <td>1</td>
      <td>5,000</td>
      <td>3-7</td>
      <td>5,000</td>
      <td>0.7962</td>
    </tr>
    <tr>
      <td>1-2</td>
      <td>15,000</td>
      <td>3-7</td>
      <td>5,000</td>
      <td>0.7985</td>
    </tr>
    <tr>
      <td>1-2</td>
      <td>20,000</td>
      <td>3-7</td>
      <td>10,000</td>
      <td>0.8005</td>
    </tr>
    <tr>
      <td>1-2</td>
      <td>20,000</td>
      <td>3-5</td>
      <td>10,000</td>
      <td>0.8015</td>
    </tr>
    <tr>
      <td>1-3</td>
      <td>20,000</td>
      <td>3-5</td>
      <td>10,000</td>
      <td>0.8013</td>
    </tr>
  </tbody>
</table>

<p>The ideal seems to be a 20,000 word ngrams in range 1-3 and 10,000 char ngrams in range 3-5, in a tie with the same settings but a 1-2 word ngram. An added benefit of these parameters is that this is a relatively fast vector to calculate.</p>

<h3 id="step-2-tune-nb-feature-weight">Step 2: Tune NB feature weight</h3>
<p>The NB feature transformer class has a parameter ‘epsilon’ that controls the influence of the
feature level probabilities on the input features. The default parameter is 1.0.</p>

<table>
  <tbody>
    <tr>
      <td><strong>NB Weight</strong></td>
      <td><strong>F1 Score</strong></td>
    </tr>
    <tr>
      <td>0.1</td>
      <td>0.7966</td>
    </tr>
    <tr>
      <td>0.2</td>
      <td>0.7989</td>
    </tr>
    <tr>
      <td>0.3</td>
      <td>0.8003</td>
    </tr>
    <tr>
      <td>0.4</td>
      <td>0.8001</td>
    </tr>
    <tr>
      <td>0.5</td>
      <td>0.8008</td>
    </tr>
    <tr>
      <td>0.6</td>
      <td>0.8013</td>
    </tr>
    <tr>
      <td>0.7</td>
      <td>0.8007</td>
    </tr>
    <tr>
      <td>0.8</td>
      <td>0.8020</td>
    </tr>
    <tr>
      <td>0.9</td>
      <td>0.8019</td>
    </tr>
    <tr>
      <td>1.0</td>
      <td>0.8015</td>
    </tr>
  </tbody>
</table>

<p>The weight of the features transformed by Naive Bayes doesn’t have much effect of the model’s performance, only about a 0.006% gain between 0.1 and 1.0. But at 1.0, it offers a nice 1.31% versus without it. My takeaway is that the information that this transformation introduces isn’t impacted much by the weight given to it, at least when combined with the SVM algorithm.</p>

<h3 id="step-3-svm-parameter-tuning">Step 3: SVM Parameter Tuning</h3>
<h4 id="parameter-1-kernel">Parameter 1: Kernel</h4>
<p>SVMs have a number of parameter options. The root option is the kernel, and other options stem from there. So far, we’ve been using a linear kernel. A linear kernel fits best to datasets where the the dataset is linearly separable, and because this model vastly outperformed a well-tuned boosted tree model (LightGBM) I assume that it has a reasonable level of linear separation.</p>

<p>This is a large dataset, and a major benefit of the linear kernel is that is is a parametric model, meaning that it has finite dimensionality regardless of the size of the input data. The gaussian kernel is better suited for nonlinear datasets, but it comes at the cost of being a non-parametric model. As the input data grows, it becomes more expensive computational to for both training and prediction.</p>

<p>Result of testing gaussian kernel: 30+ minute training on a computer with 8 virtual processors and 52GB of RAM and a slow prediction step. This is not a viable solution and will not be further pursued.</p>

<h4 id="parameter-2-penalty-for-error-term">Parameter 2: Penalty for error term</h4>
<p>Going with the linear kernel, there is only one major parameter to tune: C. This is the coefficient for the L2 penalization. The default is 1.0, and I will test 0.5, 0.7, and 0.9.</p>

<table>
  <tbody>
    <tr>
      <td><strong>C</strong></td>
      <td><strong>F1 Score</strong></td>
    </tr>
    <tr>
      <td>0.3</td>
      <td>0.8049</td>
    </tr>
    <tr>
      <td>0.5</td>
      <td>0.8054</td>
    </tr>
    <tr>
      <td>0.8</td>
      <td>0.8032</td>
    </tr>
    <tr>
      <td>1.0</td>
      <td>0.8015</td>
    </tr>
  </tbody>
</table>

<p>Setting C to 0.5 instead of the default 1.0 gives a 0.51% performance increase.</p>

<h1 id="iv-results">IV. Results</h1>
<h2 id="model-evaluation-and-validation">Model Evaluation and Validation</h2>
<p>The model has been trained, tested, and optimized using training and test subsets of the data. I will use an unseen holdout subset of the data to evaluate the model.</p>

<p>The F1 Score on the holdout data is 0.8072.</p>

<p>Because it’s performance is similar to the results obtained in the previous stage, I can confidently say that the model will generalize well to unseen data. Because it is a real world dataset with a huge variety of comments discussing a diverse range of topics and covering situations from informative posts to flame wars, this is probably one of the better scenarios for training a model on text.</p>

<p>The text vectorization strategy using Scikit-Learn’s TfidfVectorizer() class makes the model immune to unseen features, as they will be ignored.</p>

<h2 id="justification">Justification</h2>
<p>The final model offers a significant performance boost over the benchmark linear regression model, about 11%. So far we’ve been talking in the abstract about F1 Scores, but now let’s dig into the real world performance and what those numbers actually mean.</p>

<p>This model has 96% accuracy. Now on the surface, that sounds great. But since this is a highly imbalanced dataset, that doesn’t mean a lot. In fact, if I had just created a model that predicted “0” for every single item, it would get an accuracy of 90%.</p>

<p>The real metric of how well the model performed at predicting a toxic comment is recall. This model achieved a recall score of 0.74, which means that it correctly 74% of the actual toxic comments as toxic. That may seem low, but optimizing for recall is a tough challenge. If we used recall as a training objective, it would classify every comment as toxic and quickly reach 100% recall and make every clean comment a false positive. It’s necessary then to strike a balance between precision and recall. False positives waste time, while false negatives allow toxicity to fall through the cracks.</p>

<p>You can see a confusion matrix where the predictions are matched with reality below.</p>

<p><img src="/images/toxic/results heatmap.png" style="width:100%" />
<br /><em>Fig 5: Toxic Comment Confusion Matrix</em></p>

<p>As discussed before, the F1 Score provides a target that helps a model find the nuance in an imbalanced dataset between catching the positive results without focusing on them to a point where the usefulness of the model suffers. A confusion matrix can illustrate the concept of balancing true positives and true negatives, as well as accuracy, recall, and precision.</p>

<p>Let’s look finally at the impact that these results have on a moderator’s work. On the validation set, this model flagged less than 3% of the clean comments as toxic, while over 89% of the toxic comments were captured.</p>

<p>Overall, I do believe that this model is robust enough for this application and it offers a large advantage over both the standard approach of human flagging for review (though I wouldn’t eliminate that as a feature) and an out-of-the-box model. Of the comments would be submitted to a moderator review by the model, 76% are toxic.</p>

<p>I believe that this performance makes this model an effective tool that would both save moderators time and efficiently catch comments that may otherwise fall through the cracks. Each moderator could have a big impact on reducing toxicity in the Wikipedia community.</p>

<h1 id="v-conclusion">V. Conclusion</h1>

<h2 id="reflection">Reflection</h2>
<p>The process for this project was as follows:</p>
<ol>
  <li>Analyze the problem and propose a useful solution.</li>
  <li>Explore the dataset to get a better picture of how the labels are distributed, how they correlate with each other, and what defines toxic or clean comments.</li>
  <li>Develop an objective that fits a practical use case and addresses the major class imbalance.</li>
  <li>Create a baseline score with a simple logistic regression classifier.</li>
  <li>Explore the effectiveness of multiple machine learning algorithms.</li>
  <li>Select the best model based on a balance of performance and efficiency.</li>
  <li>Refine the preprocessing strategies to optimize model performance.</li>
  <li>Tune model parameters to maximize performance.</li>
  <li>Build a the final model with the best performing algorithm and parameters and test it on a holdout subset of the data.</li>
</ol>

<p>The final model offered about 11% performance gain over the initial benchmark model, which makes it an effective solution to the problem. Even more so considering that the current system in place was hand-labeling by users via a reporting function.</p>

<p>The most difficult yet most interesting aspect of the project was understanding the relationship between the size of input data and the performance of various machine learning algorithms. This Wikipedia dataset represents a fairly wide variety of input comment sizes compared to a more restricted platform like Twitter, where each comment is limited to 140 characters. Luckily, there is a large body of research around this problem and I was able to find a research paper that proposed an effective strategy for transforming the input data to get better performance in this middle ground where the text input is not necessarily long or short.</p>

<p>Because the input size varies greatly, and because Wikipedia likely has a very distinct set of demographics versus Facebook, Twitter, or other popular platforms where you may want to classify toxic comments, I don’t believe that the model would generalize very effectively. But I do think that it work well on data from other similar platforms.</p>

<h2 id="improvement">Improvement</h2>

<p>I believe that there are a number of ways that the solution could be improved.</p>

<p>Recurrent neural networks offer extremely high performance on natural language processing problems, and if the architecture for the inferrence step were implemented efficiently the computational overhead would be minimal.</p>

<p>Another great strategy could be using multiple models, a sort of divide an conquer method where the problem is divided into multiple smaller, contextual problems. While the solution laid out here generalizes to the entire dataset, no one solution will be able to generalize perfectly to the diverse variety of inputs you’ll get from Internet users. By training models on different situations, like a model that’s only been trained on short or long comments, to only detect whether a comment is toxic when profanity is present, etc, and storing them in memory, you could use a simple decision tree to feel comments into the model that would be most effective. A few that I can think of are:</p>
<ul>
  <li>Short comments</li>
  <li>Long comments</li>
  <li>“Hot” threads where the rate of commenting is high and emotions may be high</li>
  <li>Comments with profanity (A general model might flag profanity as toxic, where a model trained only on comments where profanity is present may pick up on more nuance.)</li>
  <li>Comments by a user who has already been flagged as toxic in the past</li>
</ul>

<h1 id="resources">Resources:</h1>
<ol>
  <li><a href="https://conversationai.github.io/">https://conversationai.github.io/</a></li>
  <li><a href="https://www.kaggle.com/c/jigsaw-toxic-comment-classification-challenge">https://www.kaggle.com/c/jigsaw-toxic-comment-classification-challenge</a></li>
  <li><a href="https://www.aclweb.org/anthology/P12-2018">https://www.aclweb.org/anthology/P12-2018</a></li>
  <li><a href="https://www.kdnuggets.com/2016/06/select-support-vector-machine-kernels.html">https://www.kdnuggets.com/2016/06/select-support-vector-machine-kernels.html</a></li>
</ol>]]></content><author><name>Jay Speidell</name><email>jayspeidell@gmail.com</email></author><category term="data science" /><summary type="html"><![CDATA[I performed a detailed analysis of Wikipedia comments and built a model that classifies them as toxic or nontoxic. The final model is a support vector machine that uses a Naive Bayes feature weight transformer to improve performance. The data was obtained from Kaggle.]]></summary></entry></feed>